
Tag: Apache Spark
-

Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
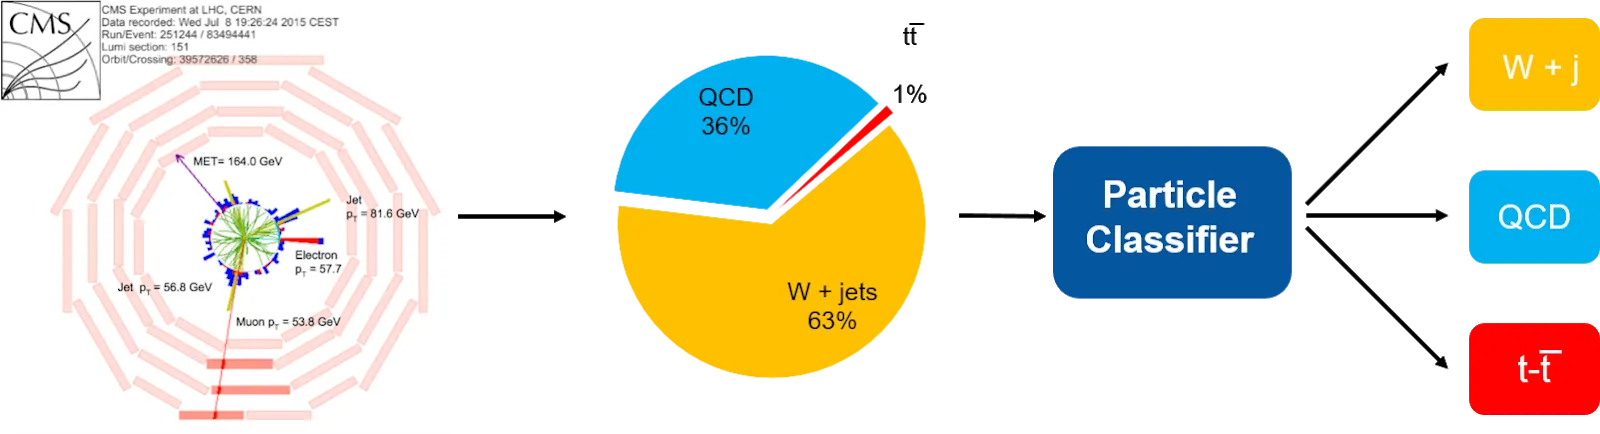
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-
A Performance Dashboard for Apache Spark
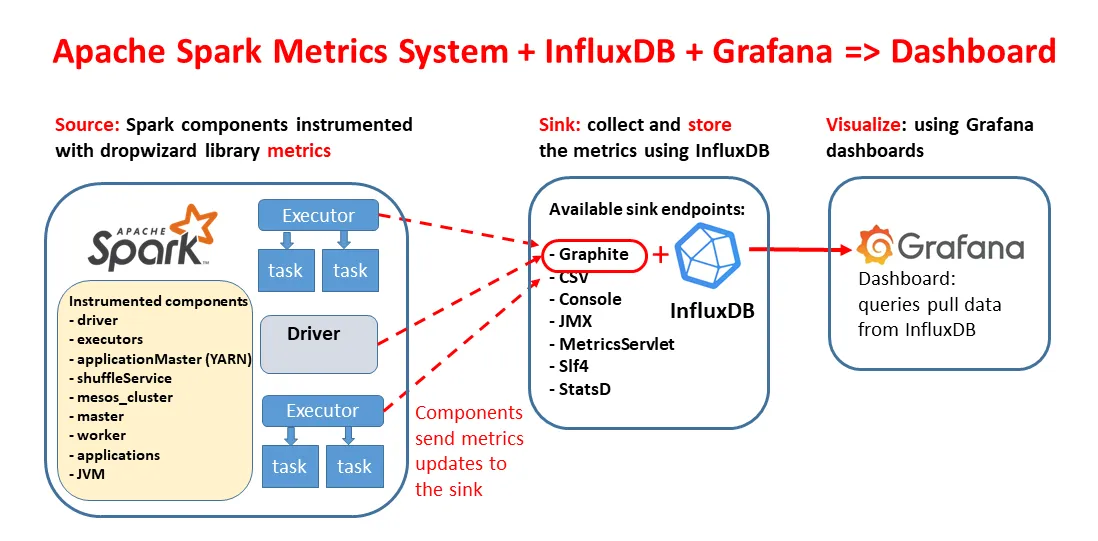
A Performance Dashboard for Apache Spark Topic: This post dives into the steps for deploying a performance dashboard for Apache Spark, using Spark metrics system instrumentation, InfluxDB and Grafana. What problem does it solve: The dashboard can provide important insights for performance troubleshooting and online monitoring of Apache Spark workloads. In particular when running Spark
-
SparkMeasure, a tool for performance troubleshooting of Apache Spark workloads
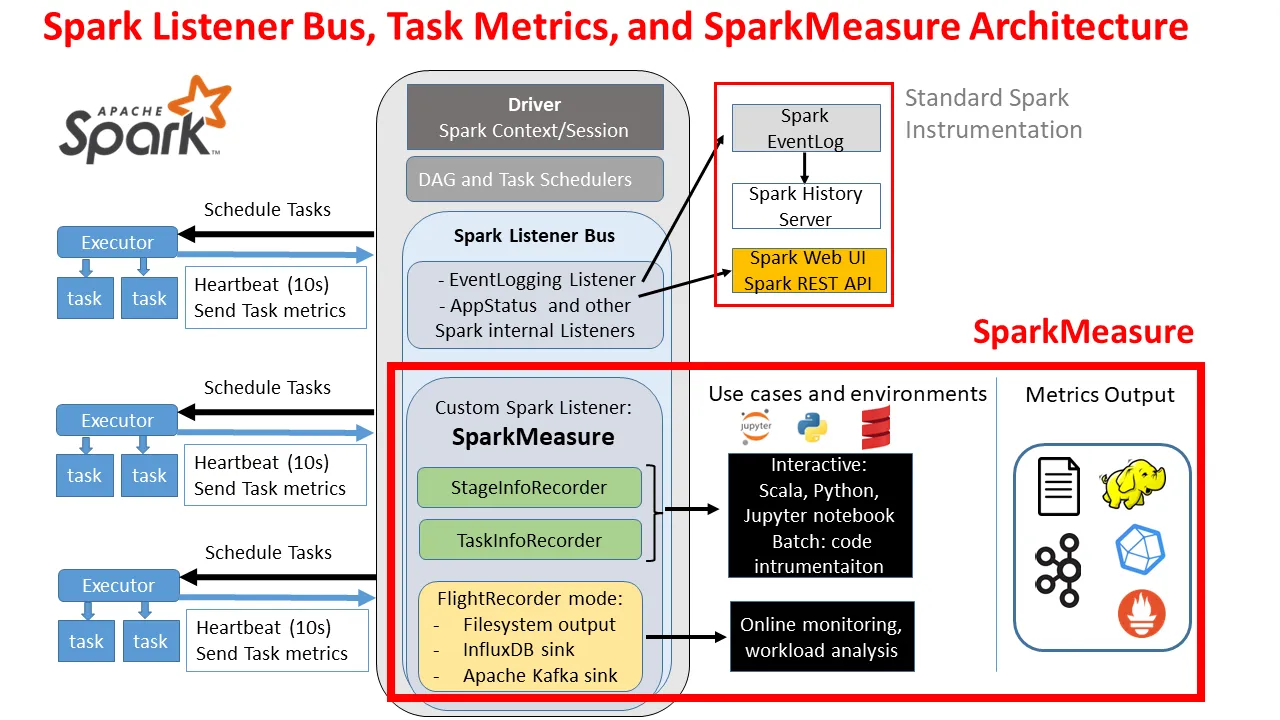
SparkMeasure, a tool for performance troubleshooting of Apache Spark workloads SparkMeasure SparkMeasure simplifies the collection and analysis of Apache Spark task metrics data. It is also intended as a working example of how to use Spark listeners for collecting and processing Spark performance metrics. The work on sparkMeasure has been previously presented in this blog
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
Diving into Spark and Parquet Workloads, by Example
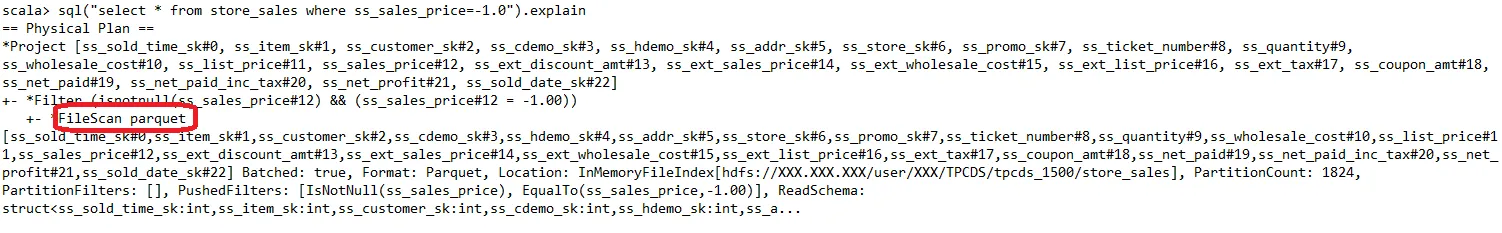
Diving into Spark and Parquet Workloads, by Example Topic: In this post you can find a few simple examples illustrating important features of Spark when reading partitioned tables stored in Parquet, in particular with a focus on performance investigations. The main topics covered are: Motivations: The combination of Spark and Parquet currently is a very