
Tag: cache
-

Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap I recently chased an Oracle performance issue where most reads were sub-millisecond (cache), but a thin band around ~10 ms (spindles) dominated total wait time. Classic bimodal latency: the fast band looked fine in averages, yet the rare slow band owned the delay. To investigate, and
-
Performance Comparison of 5 JDKs on Apache Spark
Performance Comparison of 5 JDKs on Apache Spark Dive into a comprehensive load-testing exploration using Apache Spark with CPU-intensive workloads. This blog provides a comparative analysis of five distinct JDKs’ performance under heavy-duty tasks generated through Spark. Discover a meticulous breakdown of our testing methodology, tools, and insightful results. Keep in mind, our observations primarily
-
CPU Load Testing Exercises: Tools and Analysis for Oracle Database Servers
CPU Load Testing Exercises: Tools and Analysis for Oracle Database Servers This document describes some basic CPU load testing exercises on three different types of database servers used by the Oracle Service at CERN. It reports on the tests performed, tools used for data gathering, data analysis, findings, and lessons learned. Motivations CPU usage is
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
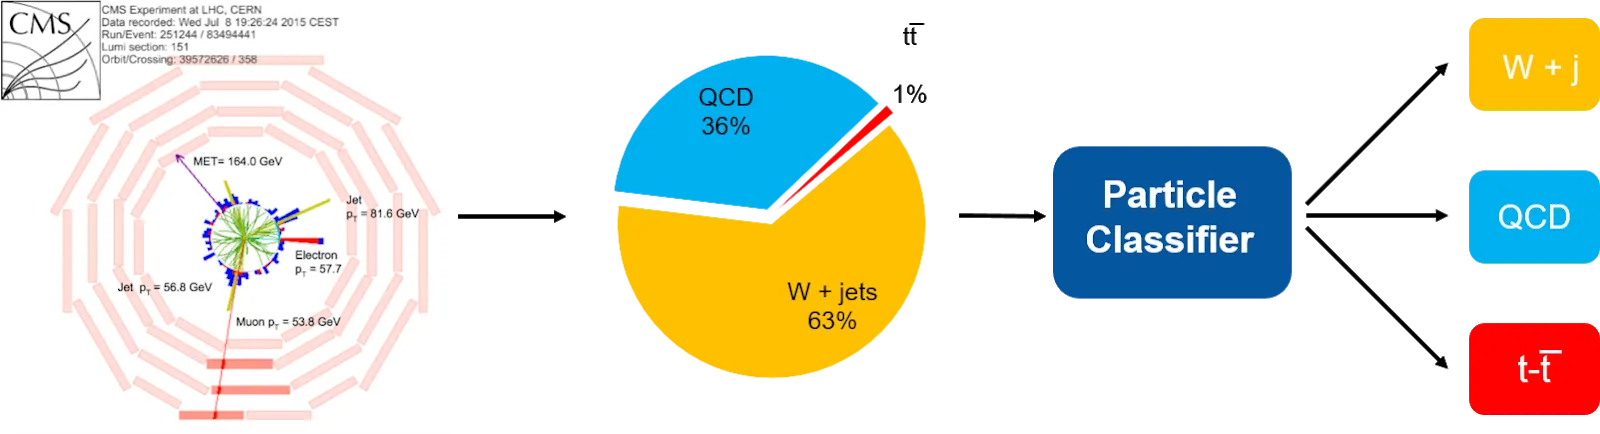
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
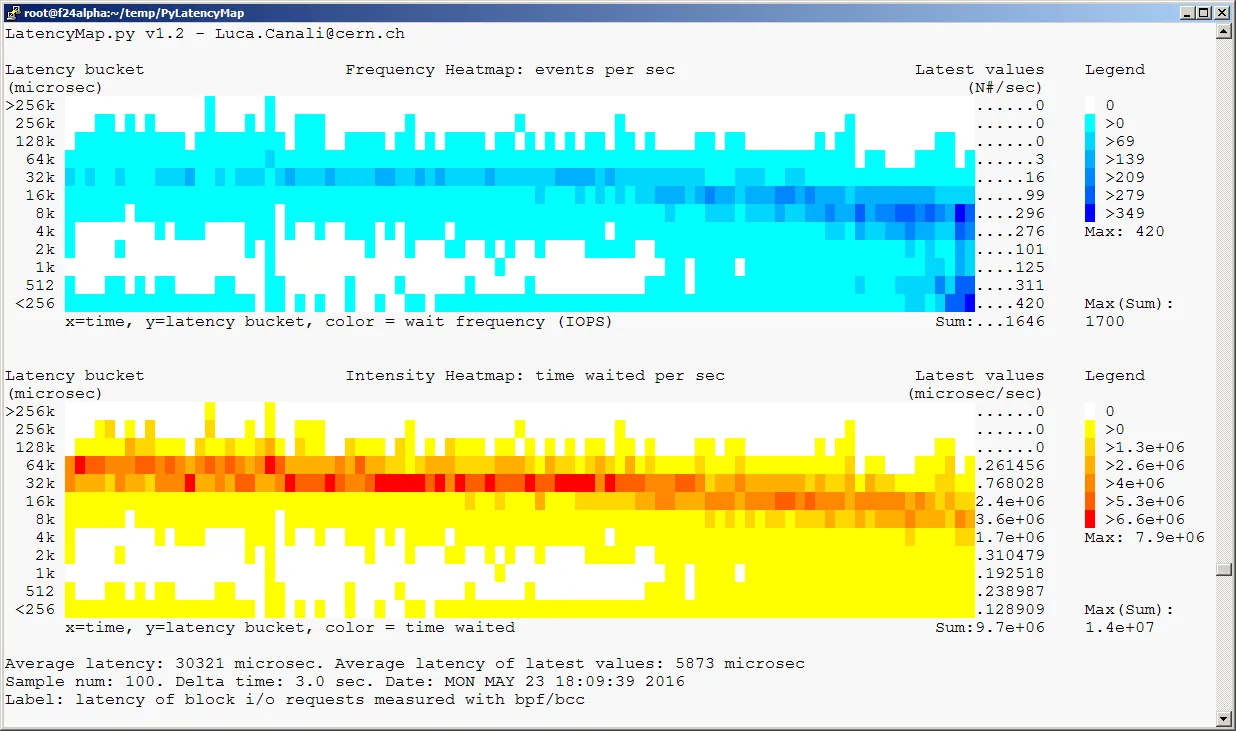
Linux BPF/bcc for Oracle Tracing
Linux BPF/bcc for Oracle Tracing Topic: In this post you will find a short discussion and pointers to the code of a few sample scripts that I have written using Linux BPF/bcc and uprobes for Oracle tracing. Previous work and motivations Tools for dynamic tracing are very useful for troubleshooting and internals investigations of Oracle
-
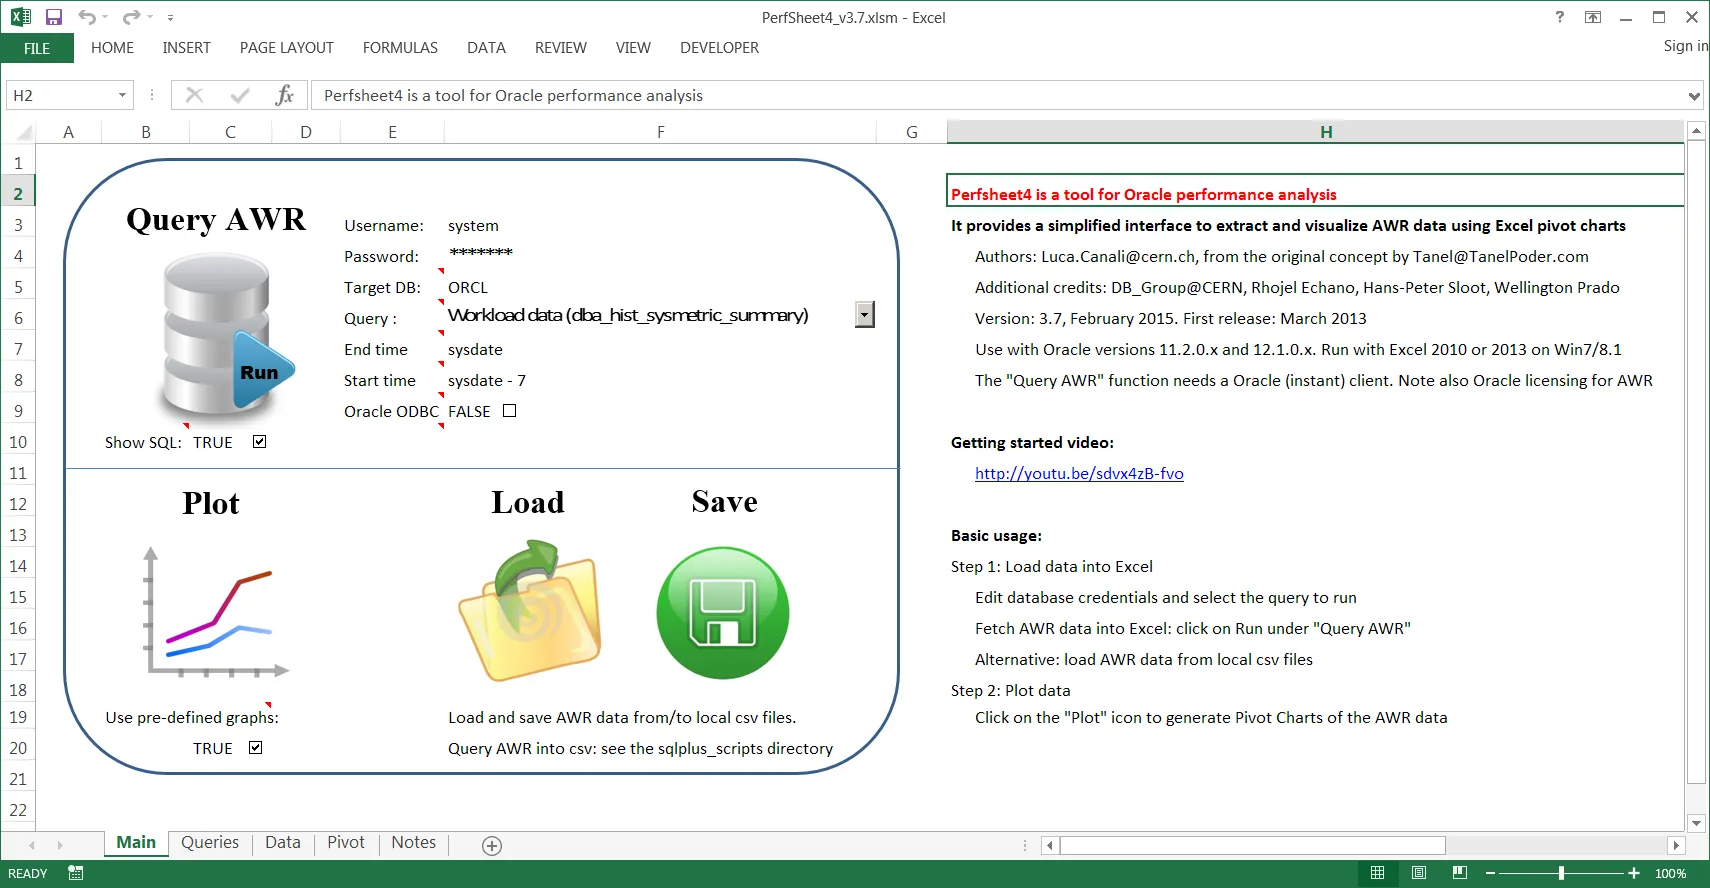
Latest updates to PerfSheet4, a tool for Oracle AWR data mining and visualization
Latest updates to PerfSheet4, a tool for Oracle AWR data mining and visualization Topic: This post is about the latest updates to PerfSheet4 v3.7 (February 2015). PerfSheet4 is a tool aimed at DBAs and Oracle performance analysts. It provides a simplified interface to extract and visualize AWR time series data using Excel pivot charts. Why
-
Scaling up Cardinality Estimates in 12.1.0.2
Scaling up Cardinality Estimates in 12.1.0.2 Topic: Counting the number of distinct values (NDV) for a table column has important applications in the database domain, ranging from query optimization to optimizing reports for large data warehouses. However the legacy SQL method of using SELECT COUNT (DISTINCT <COL>) can be very slow. This is a well
-
Flame Graphs for Oracle
Flame Graphs for Oracle Topic: This post is a hands-on introduction to using on-CPU Flame Graphs for investigating Oracle workloads. This technique is about collecting and visualizing sampled stack trace data to analyze and troubleshoot Oracle processes at the OS level (in particular applied to Linux). Motivations: The techniques and tools described here can be