
Tag: Impala
-
Offline analysis of HDFS metadata
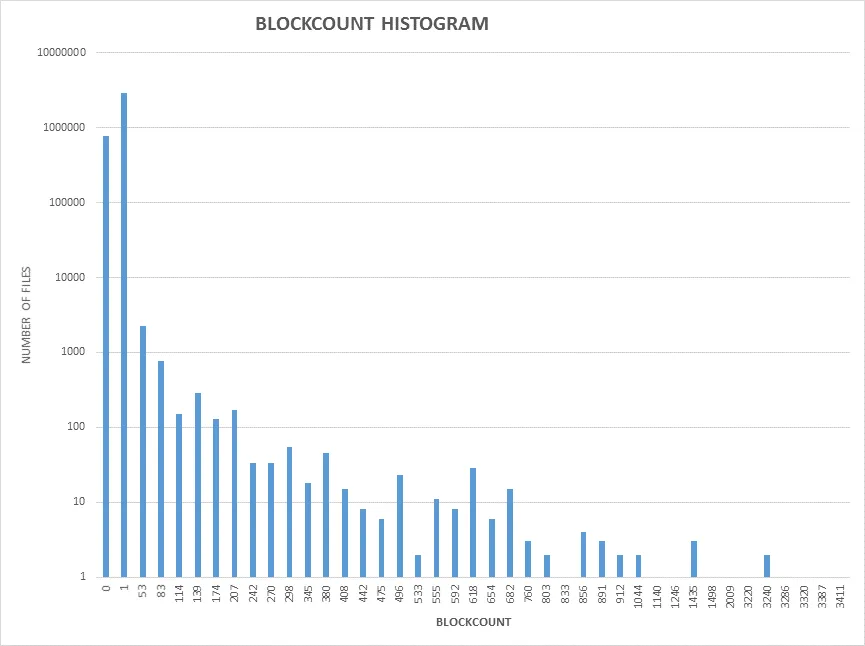
Offline analysis of HDFS metadata Introduction HDFS is part of the core Hadoop ecosystem and serves as a storage layer for the Hadoop computational frameworks like Spark, MapReduce. Like other distributed file systems, HDFS is based on an architecture where namespace is decoupled from the data. The namespace contains the file system metadata which is
-

IPython Notebooks for Querying Apache Impala
IPython Notebooks for Querying Apache Impala Topic: in this post you can find examples of how to get started with using IPython/Jupyter notebooks for querying Apache Impala. Apache Impala is an open source massively parallel processing (MPP) SQL Query Engine for Apache Hadoop. This post explores the use of IPython for querying Impala and generates
-
Hadoop performance troubleshooting with stack tracing, an introduction.
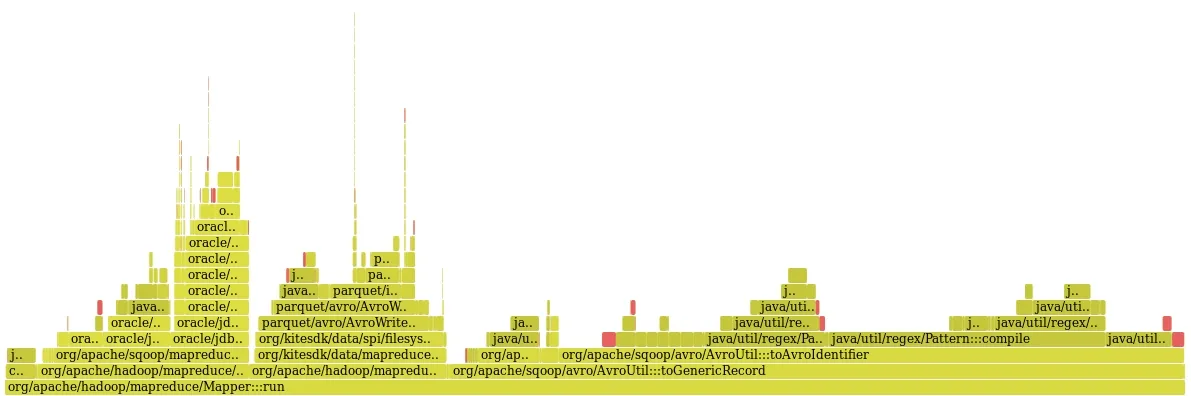
Hadoop performance troubleshooting with stack tracing, an introduction. Topic: This post is about profiling and performance tuning of distributed workloads and in particular Hadoop applications. You will learn of a profiler application we have developed and how it has successfully been applied to tuning Sqoop to improve the throughput of data transfer from Oracle to