
Tag: management
-

ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
Benefits of a multi-layer system
Benefits of a multi-layer system Introduction Designing a multi-layer system is not rocket science, the difficulty can lie in selecting the right technologies. The main concept behind the design is to have better control and fine tuning of the components. This blog post will discuss the benefits & limitations of implementing this type of design
-
A new web application for the DBOD service
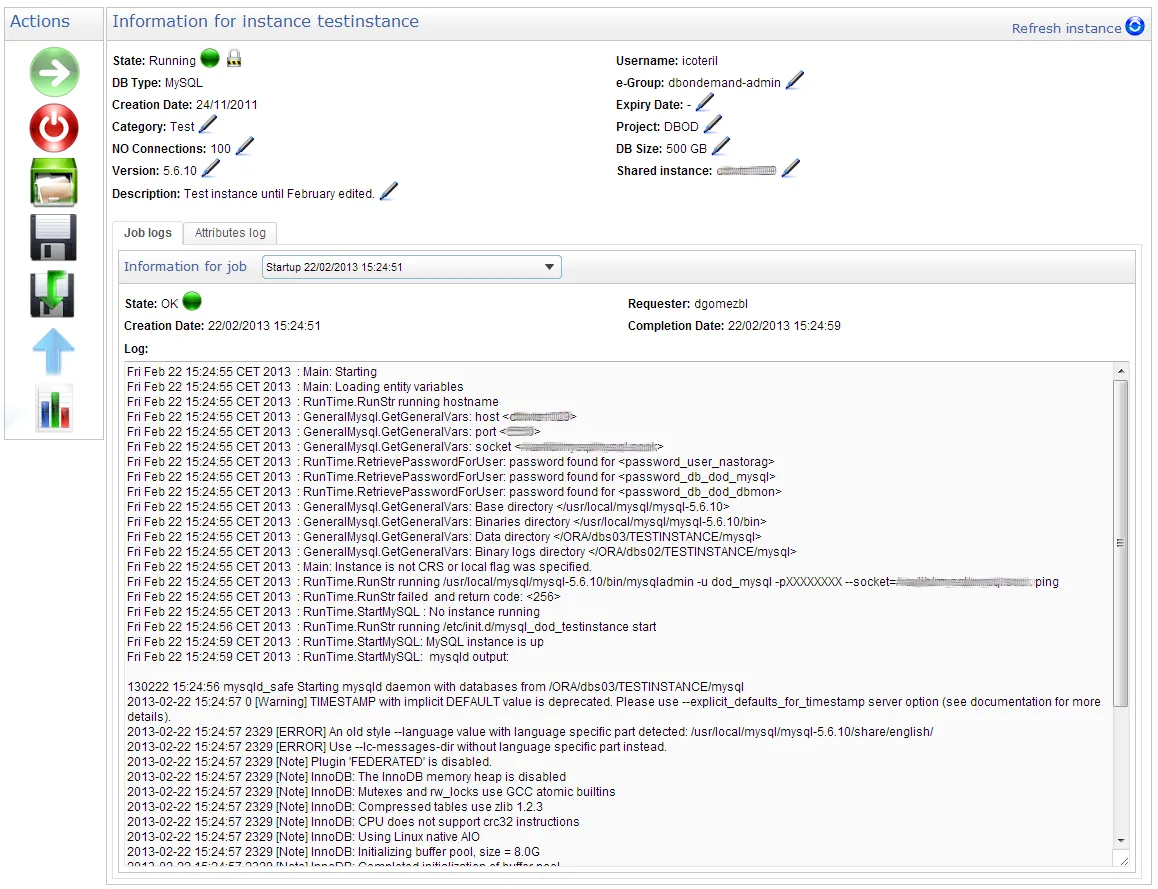
A new web application for the DBOD service Introduction The DBOD service maintains a web interface allowing “database on demand” users to carry out ordinary tasks without intervention of the administrators. It is with a view to ergonomy, but above all to modularity and scalability, that a complete redesign of this application has been initiated.
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
CERN IT-DB group develops a new WebLogic Command Line Interface tool for CERN Java Middleware Services
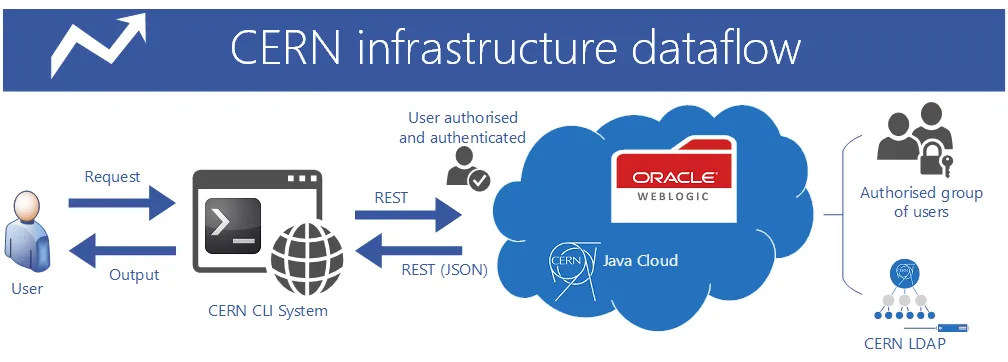
CERN IT-DB group develops a new WebLogic Command Line Interface tool for CERN Java Middleware Services Introduction CERN WebLogic CLI tool[1] is written in Python. A project is being realized in an object oriented way to contribute towards flexibility, modularity and legibility of a solution and the modules of the system are designed to maximize end-user
-
Scaling up Cardinality Estimates in 12.1.0.2
Scaling up Cardinality Estimates in 12.1.0.2 Topic: Counting the number of distinct values (NDV) for a table column has important applications in the database domain, ranging from query optimization to optimizing reports for large data warehouses. However the legacy SQL method of using SELECT COUNT (DISTINCT <COL>) can be very slow. This is a well