
Tag: Memory
-

Building an Apache Spark Performance Lab: Tools and Techniques for Spark Optimization
Building an Apache Spark Performance Lab: Tools and Techniques for Spark Optimization Apache Spark is renowned for its speed and efficiency in handling large-scale data processing. However, optimizing Spark to achieve maximum performance requires a precise understanding of its inner workings. This blog post will guide you through establishing a Spark Performance Lab with essential
-
Performance Comparison of 5 JDKs on Apache Spark
Performance Comparison of 5 JDKs on Apache Spark Dive into a comprehensive load-testing exploration using Apache Spark with CPU-intensive workloads. This blog provides a comparative analysis of five distinct JDKs’ performance under heavy-duty tasks generated through Spark. Discover a meticulous breakdown of our testing methodology, tools, and insightful results. Keep in mind, our observations primarily
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
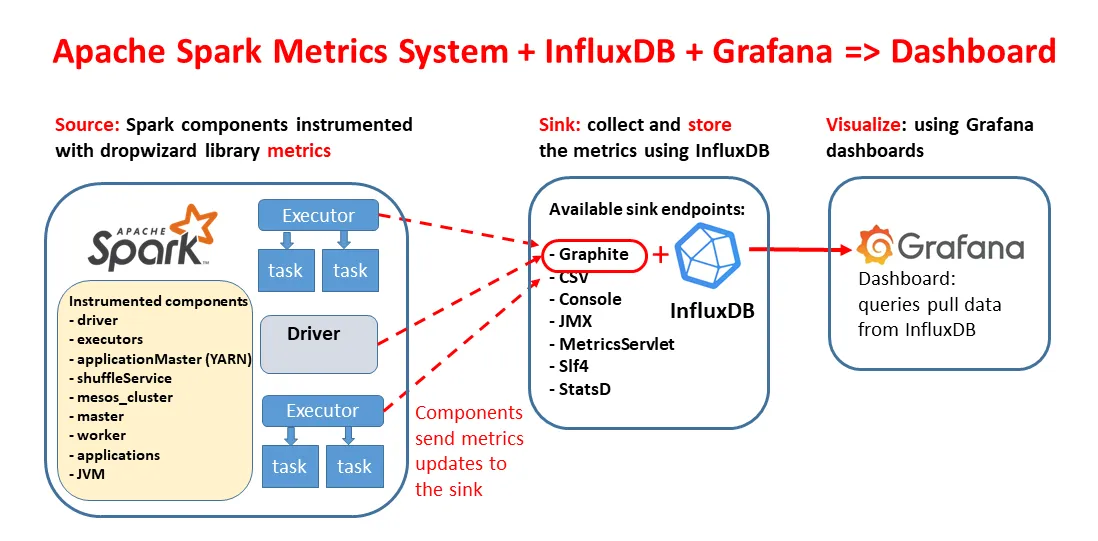
A Performance Dashboard for Apache Spark
A Performance Dashboard for Apache Spark Topic: This post dives into the steps for deploying a performance dashboard for Apache Spark, using Spark metrics system instrumentation, InfluxDB and Grafana. What problem does it solve: The dashboard can provide important insights for performance troubleshooting and online monitoring of Apache Spark workloads. In particular when running Spark
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
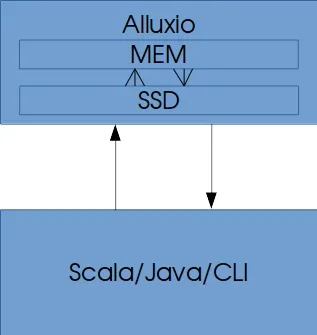
Using Tiered Storage in Alluxio
Using Tiered Storage in Alluxio Introduction Alluxio is an open source memory speed virtual distributed storage system. A brief overview of Alluxio has been covered in a previous blog. This post will cover one of the most powerful features of Alluxio, which is its tiered storage capabilities. Tiered storage allows the Alluxio volume to be
-
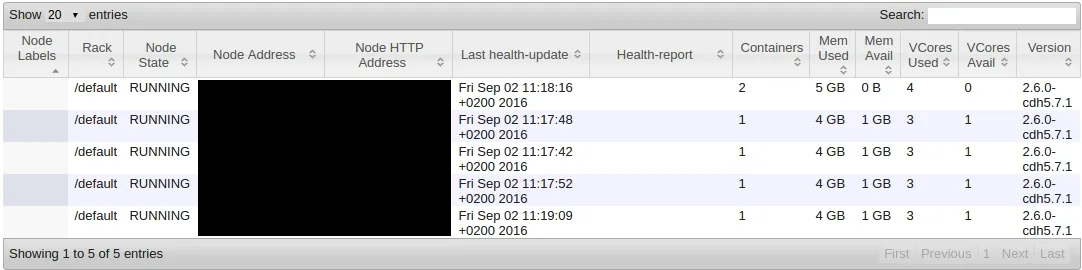
Experiences of Using Alluxio with Spark
Experiences of Using Alluxio with Spark Introduction Alluxio refers to itself as an “Open Source Memory Speed Virtual Distributed Storage” platform. It sits between the storage and processing framework layers in the distributed computing ecosystem and claims to heavily improve performance when multiple jobs are reading/writing from/to the same data. This post will cover some
-
Scaling up Cardinality Estimates in 12.1.0.2
Scaling up Cardinality Estimates in 12.1.0.2 Topic: Counting the number of distinct values (NDV) for a table column has important applications in the database domain, ranging from query optimization to optimizing reports for large data warehouses. However the legacy SQL method of using SELECT COUNT (DISTINCT <COL>) can be very slow. This is a well