
Tag: in-memory
-
Evaluation of Erasure Coding in Hadoop 3
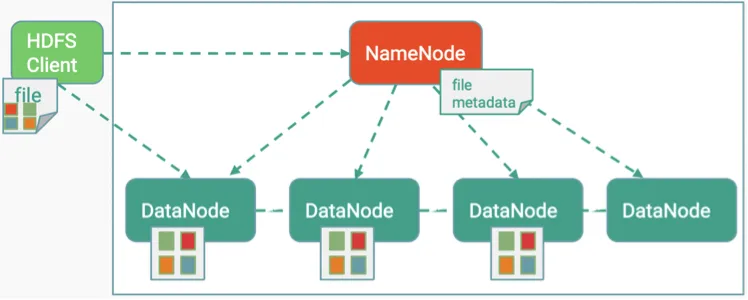
Evaluation of Erasure Coding in Hadoop 3 Authored By: Nazerke Seidan, Emil Kleszcz, Zbigniew Baranowski Published By: CERN IT-DB-SAS In this post, we will dive into the evaluation of the Erasure Coding feature of Hadoop 3 that I worked on this summer as a CERN Openlab intern. The evaluation has been performed on one of
-
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
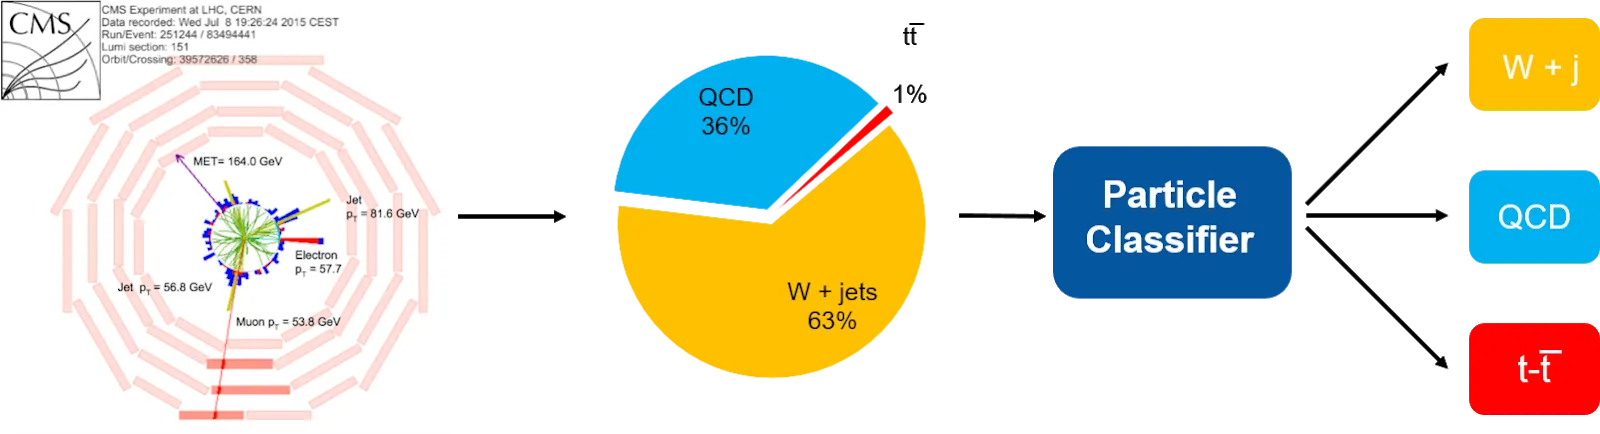
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-

Scaling up Cardinality Estimates in 12.1.0.2
Scaling up Cardinality Estimates in 12.1.0.2 Topic: Counting the number of distinct values (NDV) for a table column has important applications in the database domain, ranging from query optimization to optimizing reports for large data warehouses. However the legacy SQL method of using SELECT COUNT (DISTINCT <COL>) can be very slow. This is a well