
Tag: metadata
-

ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters In the ever-evolving landscape of big data, Apache Spark and Apache Parquet continue to introduce game-changing features. Their latest updates have brought forward significant enhancements, including column indexes, bloom filters. This blog post delves into these new features, exploring their
-
Building a Semantic Search Engine and RAG Applications with Vector Databases and Large Language Models
Building a Semantic Search Engine and RAG Applications with Vector Databases and Large Language Models This blog post is about building a getting-started example for semantic search using vector databases and large language models (LLMs), an example of retrieval augmented generation (RAG) architecture. You can find the accompanying notebook at this link. See also the
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
Creating TLS certificates using Kubernetes API
Creating TLS certificates using Kubernetes API The purpose of this post is to explain the need of adding encryption to the network communications between containers, and how to achieve it at application level, creating Transport Layer Security (TLS) certificates with the already provided Kubernetes APIs. Is it necessary to add encryption between containers? When running
-
Offline analysis of HDFS metadata
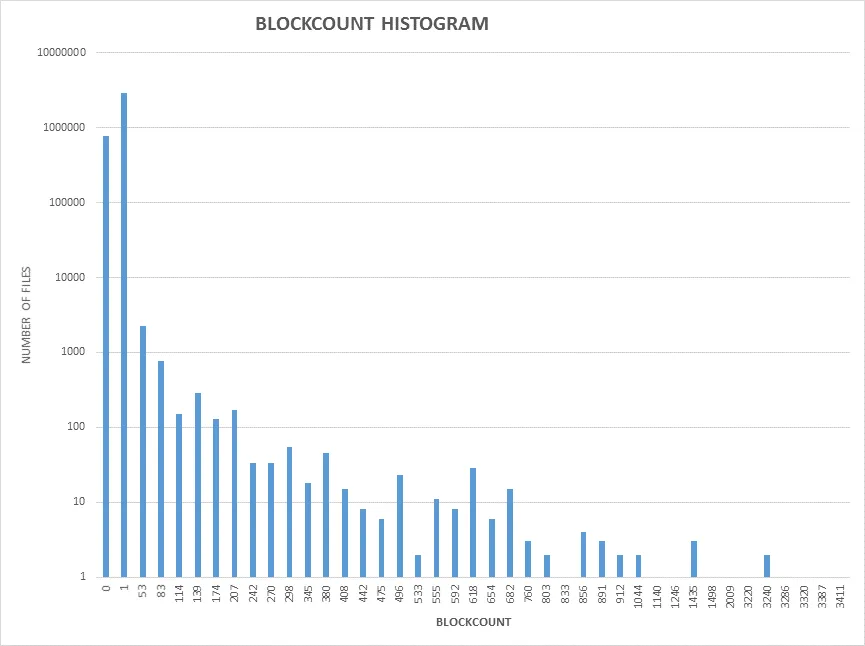
Offline analysis of HDFS metadata Introduction HDFS is part of the core Hadoop ecosystem and serves as a storage layer for the Hadoop computational frameworks like Spark, MapReduce. Like other distributed file systems, HDFS is based on an architecture where namespace is decoupled from the data. The namespace contains the file system metadata which is
-
Tool to visualise block distribution on Hadoop (HDFS) cluster
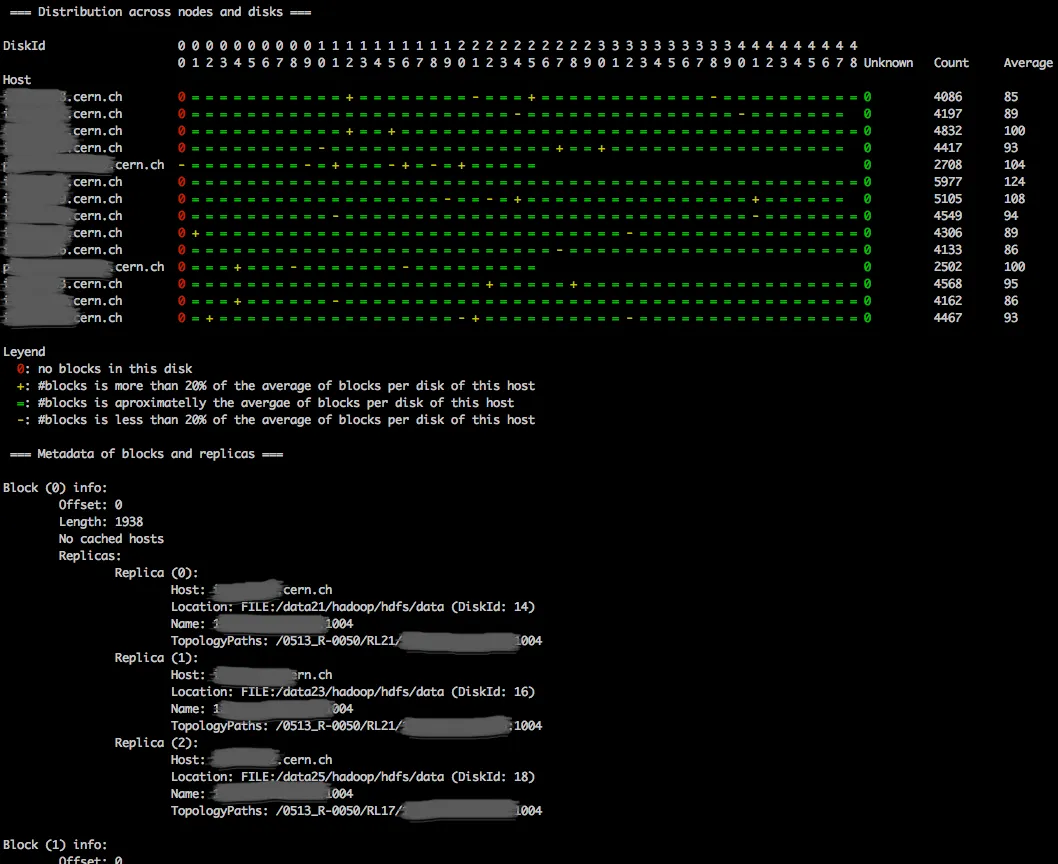
Tool to visualise block distribution on Hadoop (HDFS) cluster Distributed systems always bring new challenges for administrators and users. This is the case with HDFS, the default distributed file system that Hadoop uses for storing data. In order to face these challenges, tools to facilitate administration and usage of these systems are developed. At CERN,