
Tag: metrics
-

Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN
Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN Apache Spark is incredibly powerful, but anyone who has worked with it long enough knows the feeling: Why is this job suddenly slower today? Why are executors running out of memory? Why is one stage taking 90% of the runtime? What exactly is Spark
-
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap I recently chased an Oracle performance issue where most reads were sub-millisecond (cache), but a thin band around ~10 ms (spindles) dominated total wait time. Classic bimodal latency: the fast band looked fine in averages, yet the rare slow band owned the delay. To investigate, and
-
Building an Apache Spark Performance Lab: Tools and Techniques for Spark Optimization
Building an Apache Spark Performance Lab: Tools and Techniques for Spark Optimization Apache Spark is renowned for its speed and efficiency in handling large-scale data processing. However, optimizing Spark to achieve maximum performance requires a precise understanding of its inner workings. This blog post will guide you through establishing a Spark Performance Lab with essential
-
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters In the ever-evolving landscape of big data, Apache Spark and Apache Parquet continue to introduce game-changing features. Their latest updates have brought forward significant enhancements, including column indexes, bloom filters. This blog post delves into these new features, exploring their
-
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope TL;DR Explore a step-by-step example of troubleshooting Apache Spark job performance using flame graph visualization and profiling. Discover the seamless integration of Grafana Pyroscope with Spark for streamlined data collection and visualization. The Puzzle of the Slow Query Set within the framework
-
Performance Comparison of 5 JDKs on Apache Spark
Performance Comparison of 5 JDKs on Apache Spark Dive into a comprehensive load-testing exploration using Apache Spark with CPU-intensive workloads. This blog provides a comparative analysis of five distinct JDKs’ performance under heavy-duty tasks generated through Spark. Discover a meticulous breakdown of our testing methodology, tools, and insightful results. Keep in mind, our observations primarily
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
A Performance Dashboard for Apache Spark
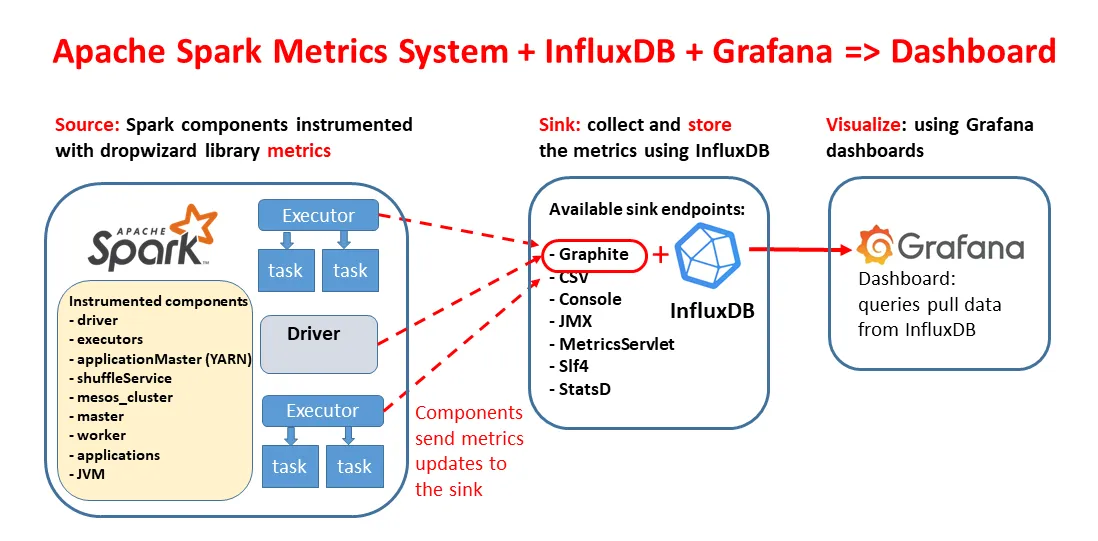
A Performance Dashboard for Apache Spark Topic: This post dives into the steps for deploying a performance dashboard for Apache Spark, using Spark metrics system instrumentation, InfluxDB and Grafana. What problem does it solve: The dashboard can provide important insights for performance troubleshooting and online monitoring of Apache Spark workloads. In particular when running Spark
-
Intelligent monitoring with a new general-purpose metrics monitor
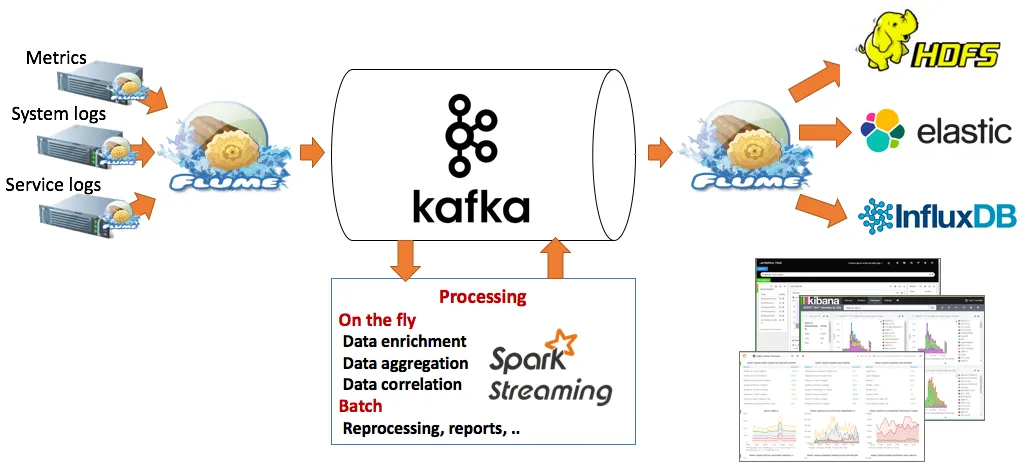
Intelligent monitoring with a new general-purpose metrics monitor In the database team at CERN, we have developed a general-purpose metrics monitor, a missing part in our next generation monitoring infrastructure. In the implemented metrics monitor, metrics can come from several sources like Apache Kafka, new metrics can be defined combining other metrics, different analysis can
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant