
Tag: pyspark
-

Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches)
Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches) TL;DR: Apache Spark 4 lets you build first-class data sources in pure Python. If your reader yields Arrow RecordBatch objects, Spark ingests them with reduced Python↔JVM serialization overhead. I used this to ship a ROOT data format reader for PySpark. A PySpark reader
-
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope TL;DR Explore a step-by-step example of troubleshooting Apache Spark job performance using flame graph visualization and profiling. Discover the seamless integration of Grafana Pyroscope with Spark for streamlined data collection and visualization. The Puzzle of the Slow Query Set within the framework
-
Apache Spark 3.0 Memory Monitoring Improvements
Apache Spark 3.0 Memory Monitoring Improvements TLDR; Apache Spark 3.0 comes with many improvements, including new features for memory monitoring. This can help you troubleshooting memory usage and optimizing the memory configuration of your Spark jobs for better performance and stability, see SPARK-23429 and SPARK-27189. The problem with memory Memory is key for the performance
-
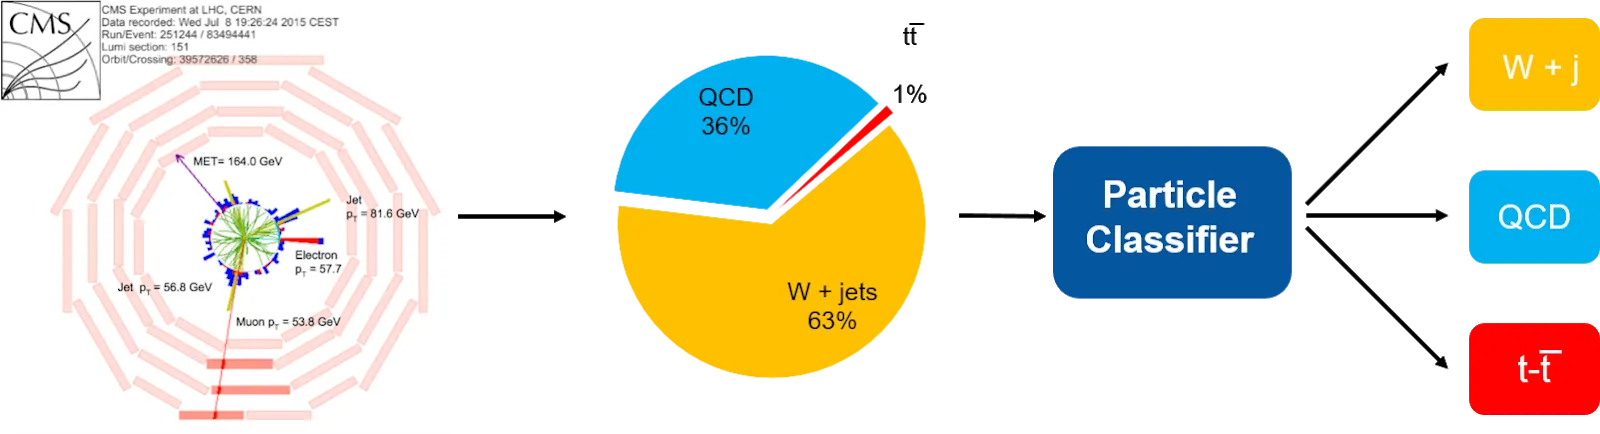
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-
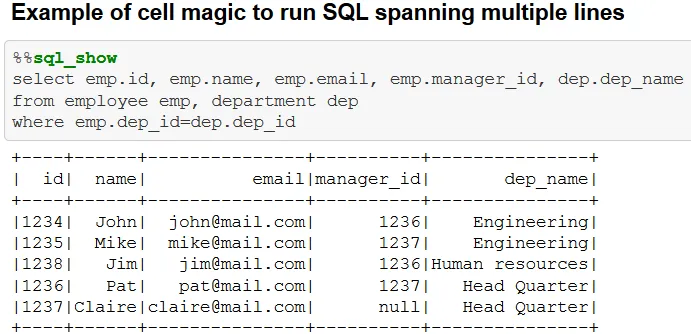
IPython/Jupyter SQL Magic Functions for PySpark
IPython/Jupyter SQL Magic Functions for PySpark Topic: this post is about a simple implementation with examples of IPython custom magic functions for running SQL in Apache Spark using PySpark and Jupyter notebooks. If you are already famialiar with Apache Spark and Jupyter notebooks may want to go directly to the links with the example notebook
-
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark Introduction In the part 2 of 'Integrating Hadoop and Elasticsearch' blogpost series we look at bridging Apache Spark and Elasticsearch. I assume that you have access to Hadoop and Elasticsearch clusters and you are faced with the challenge of