
Tag: Spark-ROOT
-

Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches)
Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches) TL;DR: Apache Spark 4 lets you build first-class data sources in pure Python. If your reader yields Arrow RecordBatch objects, Spark ingests them with reduced Python↔JVM serialization overhead. I used this to ship a ROOT data format reader for PySpark. A PySpark reader
-
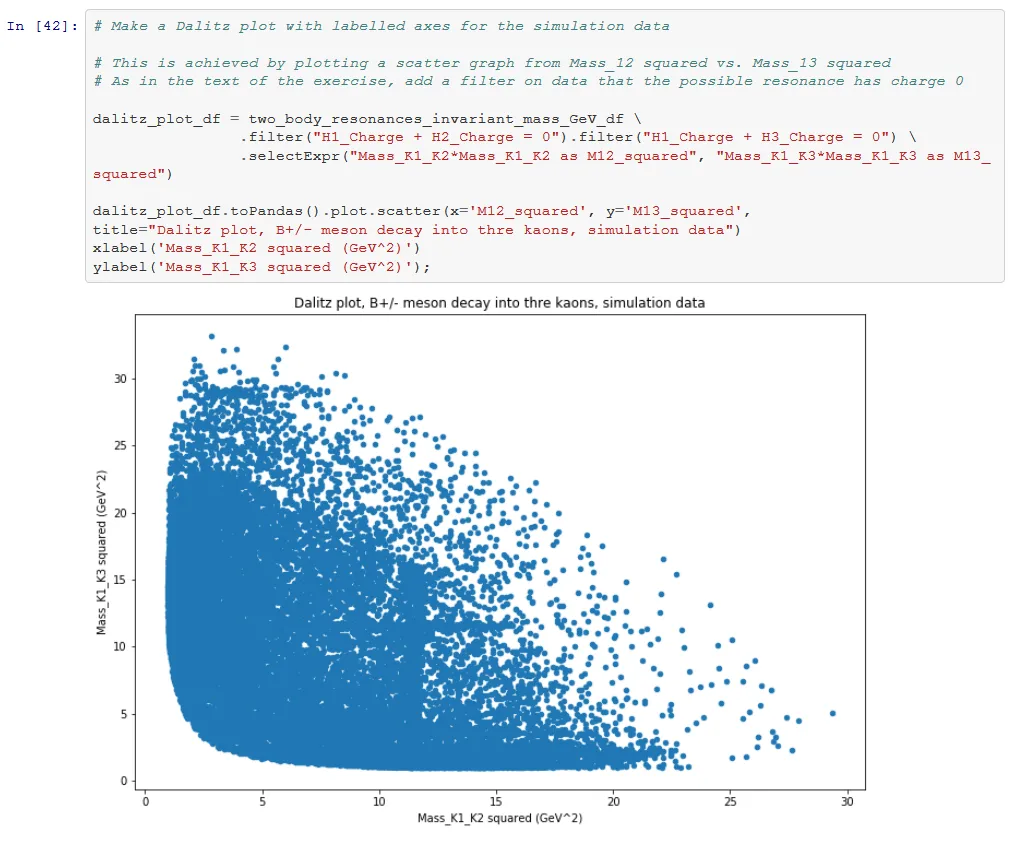
Apache Spark and CERN Open Data Analysis, an Example
Apache Spark and CERN Open Data Analysis, an Example This is a short post introducing a notebook that you can use to play with a simple analysis of High Energy Physics (HEP) data using CERN open data and Apache Spark. The idea for this work started with a concept for a technology demonstrator of some