
Tag: spark
-
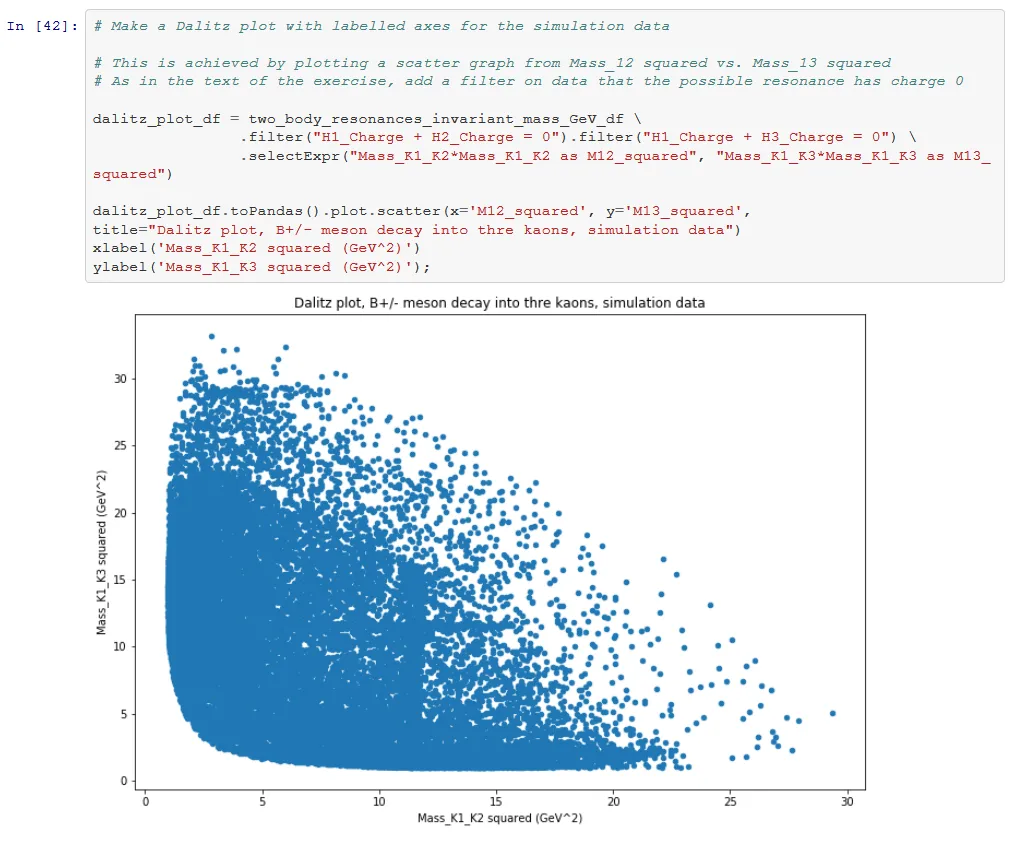
Apache Spark and CERN Open Data Analysis, an Example
Apache Spark and CERN Open Data Analysis, an Example This is a short post introducing a notebook that you can use to play with a simple analysis of High Energy Physics (HEP) data using CERN open data and Apache Spark. The idea for this work started with a concept for a technology demonstrator of some
-
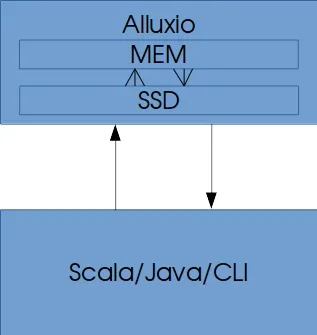
Using Tiered Storage in Alluxio
Using Tiered Storage in Alluxio Introduction Alluxio is an open source memory speed virtual distributed storage system. A brief overview of Alluxio has been covered in a previous blog. This post will cover one of the most powerful features of Alluxio, which is its tiered storage capabilities. Tiered storage allows the Alluxio volume to be
-
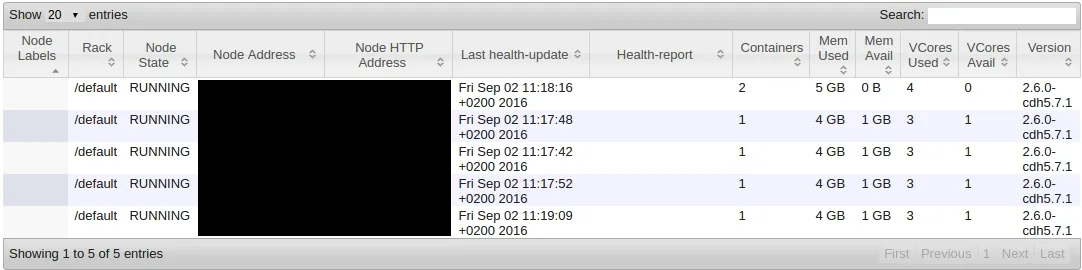
Experiences of Using Alluxio with Spark
Experiences of Using Alluxio with Spark Introduction Alluxio refers to itself as an “Open Source Memory Speed Virtual Distributed Storage” platform. It sits between the storage and processing framework layers in the distributed computing ecosystem and claims to heavily improve performance when multiple jobs are reading/writing from/to the same data. This post will cover some
-

Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark Introduction In the part 2 of 'Integrating Hadoop and Elasticsearch' blogpost series we look at bridging Apache Spark and Elasticsearch. I assume that you have access to Hadoop and Elasticsearch clusters and you are faced with the challenge of