
Tag: SQL
-

Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN
Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN Apache Spark is incredibly powerful, but anyone who has worked with it long enough knows the feeling: Why is this job suddenly slower today? Why are executors running out of memory? Why is one stage taking 90% of the runtime? What exactly is Spark
-
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap I recently chased an Oracle performance issue where most reads were sub-millisecond (cache), but a thin band around ~10 ms (spindles) dominated total wait time. Classic bimodal latency: the fast band looked fine in averages, yet the rare slow band owned the delay. To investigate, and
-
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope TL;DR Explore a step-by-step example of troubleshooting Apache Spark job performance using flame graph visualization and profiling. Discover the seamless integration of Grafana Pyroscope with Spark for streamlined data collection and visualization. The Puzzle of the Slow Query Set within the framework
-
Performance Comparison of 5 JDKs on Apache Spark
Performance Comparison of 5 JDKs on Apache Spark Dive into a comprehensive load-testing exploration using Apache Spark with CPU-intensive workloads. This blog provides a comparative analysis of five distinct JDKs’ performance under heavy-duty tasks generated through Spark. Discover a meticulous breakdown of our testing methodology, tools, and insightful results. Keep in mind, our observations primarily
-
CPU Load Testing Exercises: Tools and Analysis for Oracle Database Servers
CPU Load Testing Exercises: Tools and Analysis for Oracle Database Servers This document describes some basic CPU load testing exercises on three different types of database servers used by the Oracle Service at CERN. It reports on the tests performed, tools used for data gathering, data analysis, findings, and lessons learned. Motivations CPU usage is
-
ORDS – Managing APEX static images
ORDS – Managing APEX static images In today’s post, we’ll be talking about the possible ways to manage the static images/CSS/JS that come shipped with APEX, when running on ORDS. They are separate resources (not contained in the DB like some other APEX images) necessary for your APEX applications look and behave the way they’re
-
Building and documenting REST APIs with ORDS
Building and documenting REST APIs with ORDS Introduction In the first part of the article we will provide an overview of how you can use Oracle REST Data Services for providing APIs directly from your PL/SQL code . The second part covers how to document our Web services using Swagger. Lets begin with a couple
-
Evaluation of Erasure Coding in Hadoop 3
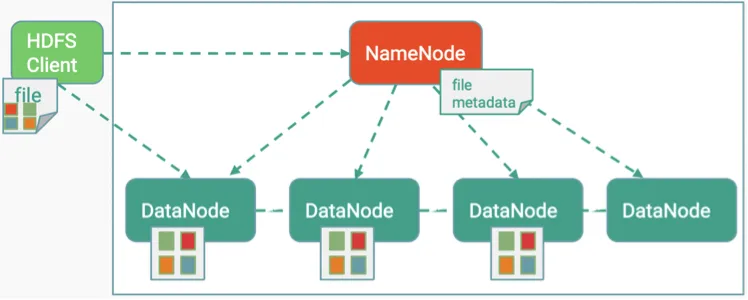
Evaluation of Erasure Coding in Hadoop 3 Authored By: Nazerke Seidan, Emil Kleszcz, Zbigniew Baranowski Published By: CERN IT-DB-SAS In this post, we will dive into the evaluation of the Erasure Coding feature of Hadoop 3 that I worked on this summer as a CERN Openlab intern. The evaluation has been performed on one of
-
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
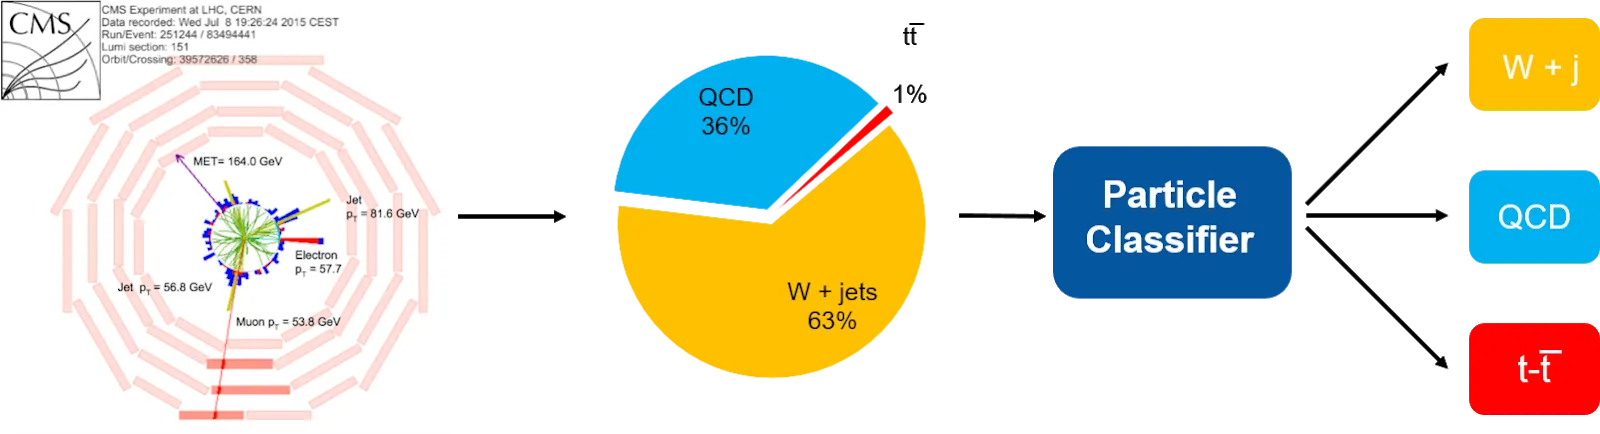
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data