
Tag: SSD
-

Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap
Troubleshoot I/O & Wait Latency with OraLatencyMap and PyLatencyMap I recently chased an Oracle performance issue where most reads were sub-millisecond (cache), but a thin band around ~10 ms (spindles) dominated total wait time. Classic bimodal latency: the fast band looked fine in averages, yet the rare slow band owned the delay. To investigate, and
-
Evaluation of Erasure Coding in Hadoop 3
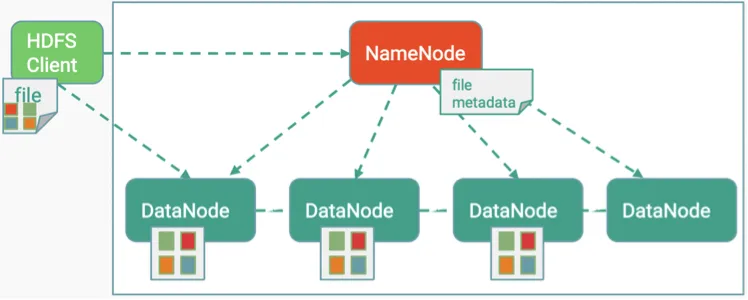
Evaluation of Erasure Coding in Hadoop 3 Authored By: Nazerke Seidan, Emil Kleszcz, Zbigniew Baranowski Published By: CERN IT-DB-SAS In this post, we will dive into the evaluation of the Erasure Coding feature of Hadoop 3 that I worked on this summer as a CERN Openlab intern. The evaluation has been performed on one of
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
Using Tiered Storage in Alluxio
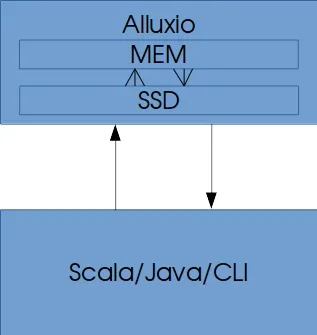
Using Tiered Storage in Alluxio Introduction Alluxio is an open source memory speed virtual distributed storage system. A brief overview of Alluxio has been covered in a previous blog. This post will cover one of the most powerful features of Alluxio, which is its tiered storage capabilities. Tiered storage allows the Alluxio volume to be
-
Experiences of Using Alluxio with Spark
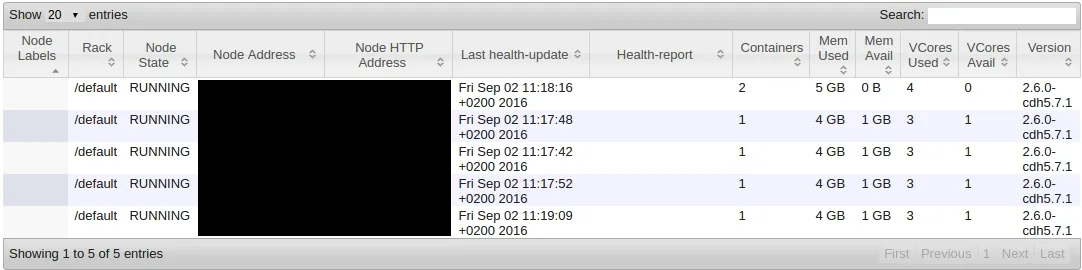
Experiences of Using Alluxio with Spark Introduction Alluxio refers to itself as an “Open Source Memory Speed Virtual Distributed Storage” platform. It sits between the storage and processing framework layers in the distributed computing ecosystem and claims to heavily improve performance when multiple jobs are reading/writing from/to the same data. This post will cover some
-
Linux BPF/bcc for Oracle Tracing
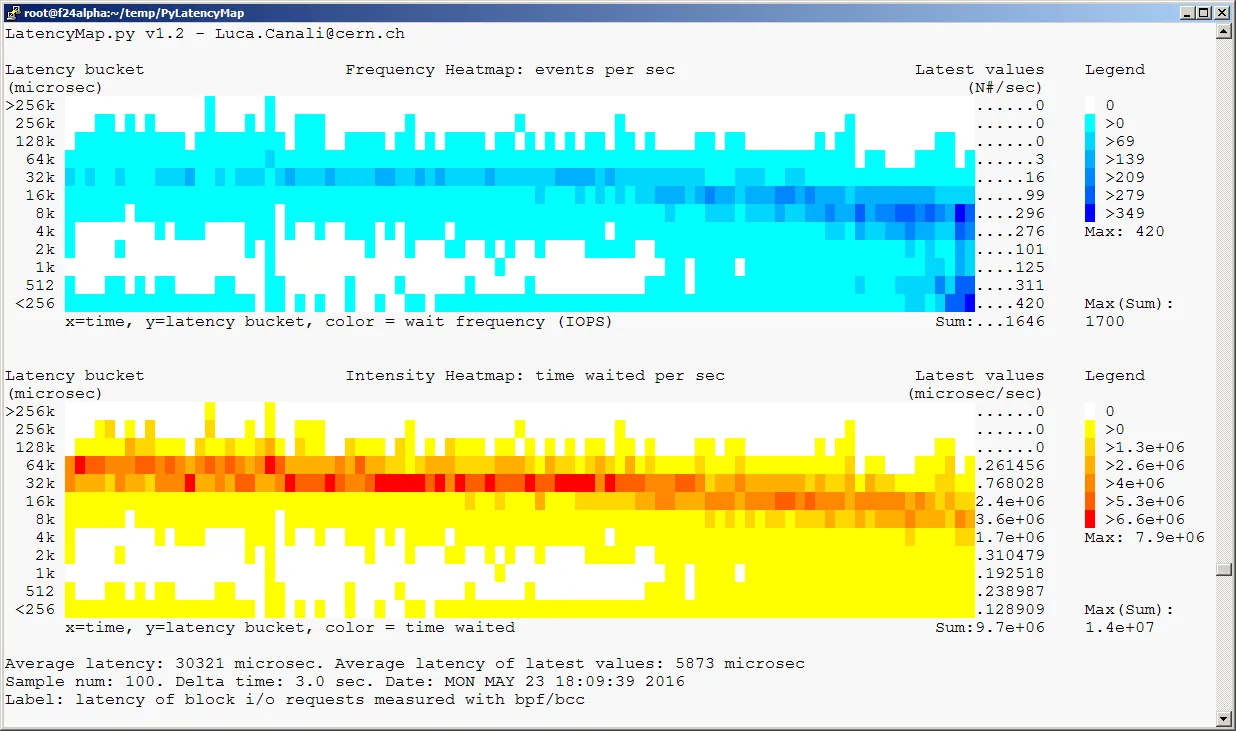
Linux BPF/bcc for Oracle Tracing Topic: In this post you will find a short discussion and pointers to the code of a few sample scripts that I have written using Linux BPF/bcc and uprobes for Oracle tracing. Previous work and motivations Tools for dynamic tracing are very useful for troubleshooting and internals investigations of Oracle
-
A Closer Look at CALIBRATE_IO
A Closer Look at CALIBRATE_IO Topic: This blog entry is about investigating Oracle’s DBMS_RESOURCE_MANAGER.CALIBRATE_IO Spoiler: For quantitative analysis of storage performance and in particular for measuring random read I/O in Oracle, I’d rather advise the use tools that allow generating test workloads in a controlled manner, in a way that can be understood and measured