
Introduction to Apache Spark APIs for Data Processing

Welcome to the website of the course on Apache Spark by CERN IT. The course is self-paced and open, it is a short introduction to the architecture and key abstractions used by Spark. Theory and demos cover the main Spark APIs: DataFrame API, Spark SQL, Streaming, Machine Learning. You will also learn how to deploy Spark on CERN computing resources, notably using the CERN SWAN service. Most tutorials and exercises are in Python and run on Jupyter notebooks.
Apache Spark is a popular engine for data processing at scale. Spark provides an expressive API and a scalable engine that integrates very well with the Hadoop ecosystem as well as with Cloud resources. Spark is currently used by several projects at CERN, notably by IT monitoring, by the security team, by the BE NXCALS project, by teams in ATLAS and CMS. Moreover, Spark is integrated with the CERN Hadoop service, the CERN Cloud service, and the CERN SWAN web notebooks service.
Accompanying notebooks
- Get the notebooks from:
- How to run the notebooks:
- CERN SWAN (recommended option):
- Colab
 , Binder
- Local/private Jupyter notebook
- See also the SWAN gallery and the video:
- CERN SWAN (recommended option):
Course lectures and tutorials
- Introduction and objectives: slides and video
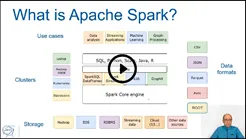
- Session 1: Apache Spark fundamentals
- Session 2: Working with Spark DataFrames and SQL
- Session 3: Building on top of the DataFrame API
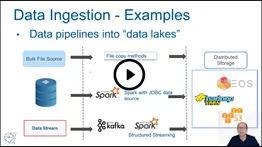
- Lecture “Spark as a Data Platform”: slides and video
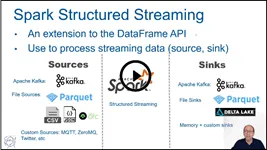
- Lecture “Spark Streaming”: slides and video
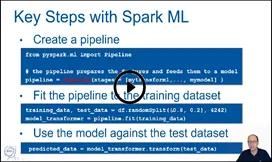
- Lecture “Spark and Machine Learning”: slides and video
- Notebooks:
- Tutorial on Spark Streaming – video

- Tutorial on Spark Machine Learning – regression task – video

- Tutorial on Spark Machine Learning – classification task with the Higgs dataset
- Demo of the Spark JDBC data source how to read Oracle tables from Spark
- Tutorial on Spark Streaming – video
- Note on Spark and Parquet format
- Lecture “Spark as a Data Platform”: slides and video
- Session 4: How to scale out Spark jobs
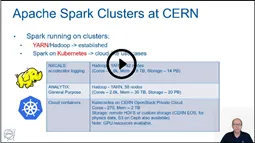
- Lecture “Running Spark on CERN resources”: slides and video
- Notebooks:
- Demo on using SWAN with Spark on Hadoop – video

- Demo of Spark processing Physics data using CERN private Cloud resources – video

- Example notebook for the NXCALS project
- Demo on using SWAN with Spark on Hadoop – video
- Lecture “Running Spark on CERN resources”: slides and video


- Bonus material:
- How to monitor Spark execution: slides and video

- Spark as a library, examples of how to use Spark in Scala and Python programs: code and video
- Next steps: reading material and links, miscellaneous Spark notes
- How to monitor Spark execution: slides and video
- Read and watch at your pace:
- Download the course material for offline use:
slides.zip, github_repo.zip, videos.zip - Watch the videos on YouTube

- Download the course material for offline use:
Acknowledgements and feedback
Author and contact for feedback and questions: Luca Canali – Luca.Canali@cern.ch
CERN-IT Spark and data analytics services
Former contributors: Riccardo Castellotti, Prasanth Kothuri
Many thanks to CERN Technical Training for their collaboration and support
License: CC BY-SA 4.0
Published in November 2022