
Tag: Jupyter notebook
-

Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN
Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN Apache Spark is incredibly powerful, but anyone who has worked with it long enough knows the feeling: Why is this job suddenly slower today? Why are executors running out of memory? Why is one stage taking 90% of the runtime? What exactly is Spark
-
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Kepler’s Mars Orbit Analysis with Python Notebooks & AI-Assisted Coding
Kepler’s Mars Orbit Analysis with Python Notebooks & AI-Assisted Coding Johannes Kepler ’s analysis of Mars’ orbit stands as one of the greatest achievements in scientific history, revealing the elliptical nature of planetary paths and establishing the foundational laws of planetary motion. In this post, you will explore how you can recreate Kepler’s revolutionary findings
-
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope TL;DR Explore a step-by-step example of troubleshooting Apache Spark job performance using flame graph visualization and profiling. Discover the seamless integration of Grafana Pyroscope with Spark for streamlined data collection and visualization. The Puzzle of the Slow Query Set within the framework
-
Building a Semantic Search Engine and RAG Applications with Vector Databases and Large Language Models
Building a Semantic Search Engine and RAG Applications with Vector Databases and Large Language Models This blog post is about building a getting-started example for semantic search using vector databases and large language models (LLMs), an example of retrieval augmented generation (RAG) architecture. You can find the accompanying notebook at this link. See also the
-
Exploratory Notebooks for Deep Learning, AI, and Data Tools: A Beginner’s Guide
Exploratory Notebooks for Deep Learning, AI, and Data Tools: A Beginner’s Guide Are you looking at some resources to get you up to speed with popular Deep Learning and Data processing frameworks? This blog entry provides a curated collection of notebooks that will help you kickstart your journey. You can find the notebooks at this
-

Introduction to Apache Spark APIs for Data Processing
Introduction to Apache Spark APIs for Data Processing Welcome to the website of the course on Apache Spark by CERN IT. The course is self-paced and open, it is a short introduction to the architecture and key abstractions used by Spark. Theory and demos cover the main Spark APIs: DataFrame API, Spark SQL, Streaming, Machine
-
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
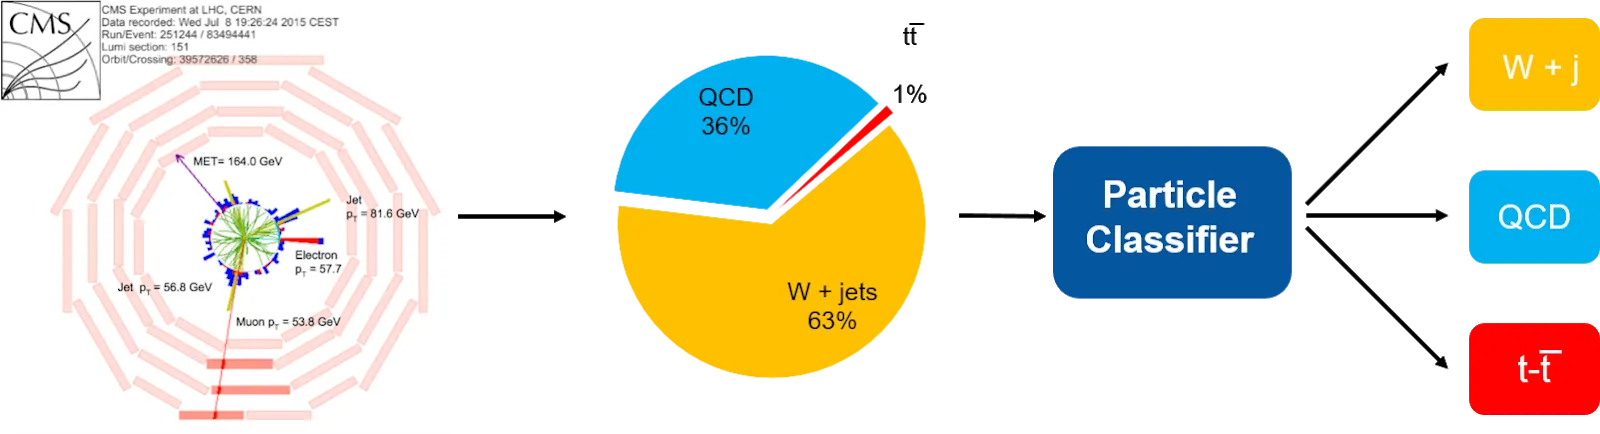
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-
Apache Spark and CERN Open Data Analysis, an Example
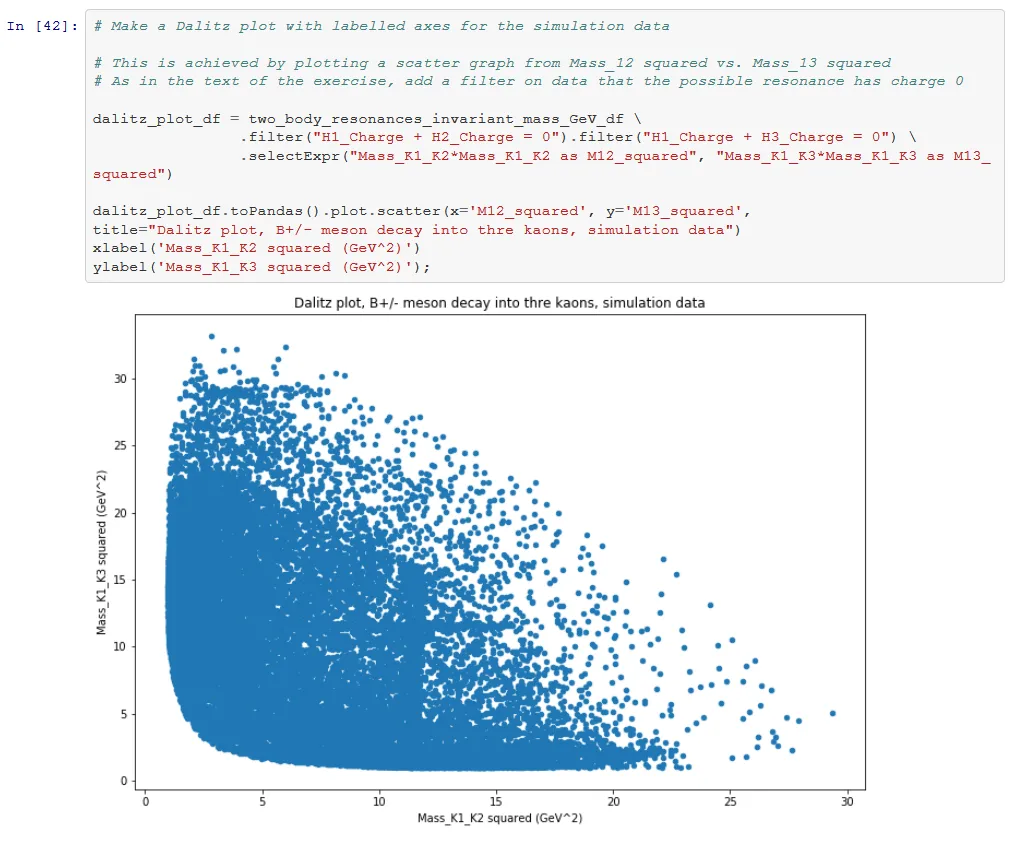
Apache Spark and CERN Open Data Analysis, an Example This is a short post introducing a notebook that you can use to play with a simple analysis of High Energy Physics (HEP) data using CERN open data and Apache Spark. The idea for this work started with a concept for a technology demonstrator of some