
Tag: Hadoop
-

Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN
Unlocking Apache Spark Performance: Three Open-Source Tools We Use at CERN Apache Spark is incredibly powerful, but anyone who has worked with it long enough knows the feeling: Why is this job suddenly slower today? Why are executors running out of memory? Why is one stage taking 90% of the runtime? What exactly is Spark
-
Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches)
Why I’m Loving Spark 4’s Python Data Source (with Direct Arrow Batches) TL;DR: Apache Spark 4 lets you build first-class data sources in pure Python. If your reader yields Arrow RecordBatch objects, Spark ingests them with reduced Python↔JVM serialization overhead. I used this to ship a ROOT data format reader for PySpark. A PySpark reader
-
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks
ATLAS DCS Analysis with Apache Spark and Jupyter Notebooks The ATLAS Detector Control System (DCS) at CERN is essential for ensuring optimal detector performance. Each year, the system generates tens of billions of time-stamped sensor readings, presenting considerable challenges for large-scale data analysis. Although these data are stored in Oracle databases that excel in real-time
-
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters
Enhancing Apache Spark and Parquet Efficiency: A Deep Dive into Column Indexes and Bloom Filters In the ever-evolving landscape of big data, Apache Spark and Apache Parquet continue to introduce game-changing features. Their latest updates have brought forward significant enhancements, including column indexes, bloom filters. This blog post delves into these new features, exploring their
-
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope
Enhancing Apache Spark Performance with Flame Graphs: A Practical Example Using Grafana Pyroscope TL;DR Explore a step-by-step example of troubleshooting Apache Spark job performance using flame graph visualization and profiling. Discover the seamless integration of Grafana Pyroscope with Spark for streamlined data collection and visualization. The Puzzle of the Slow Query Set within the framework
-
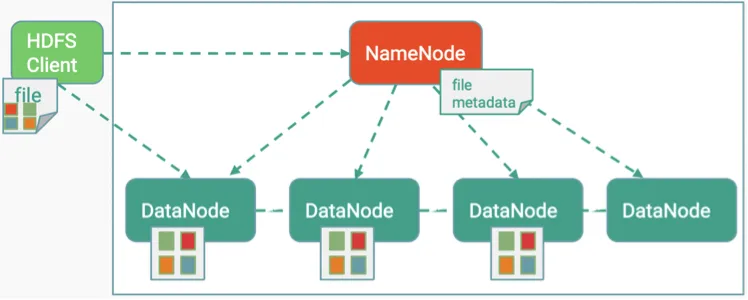
Evaluation of Erasure Coding in Hadoop 3
Evaluation of Erasure Coding in Hadoop 3 Authored By: Nazerke Seidan, Emil Kleszcz, Zbigniew Baranowski Published By: CERN IT-DB-SAS In this post, we will dive into the evaluation of the Erasure Coding feature of Hadoop 3 that I worked on this summer as a CERN Openlab intern. The evaluation has been performed on one of
-
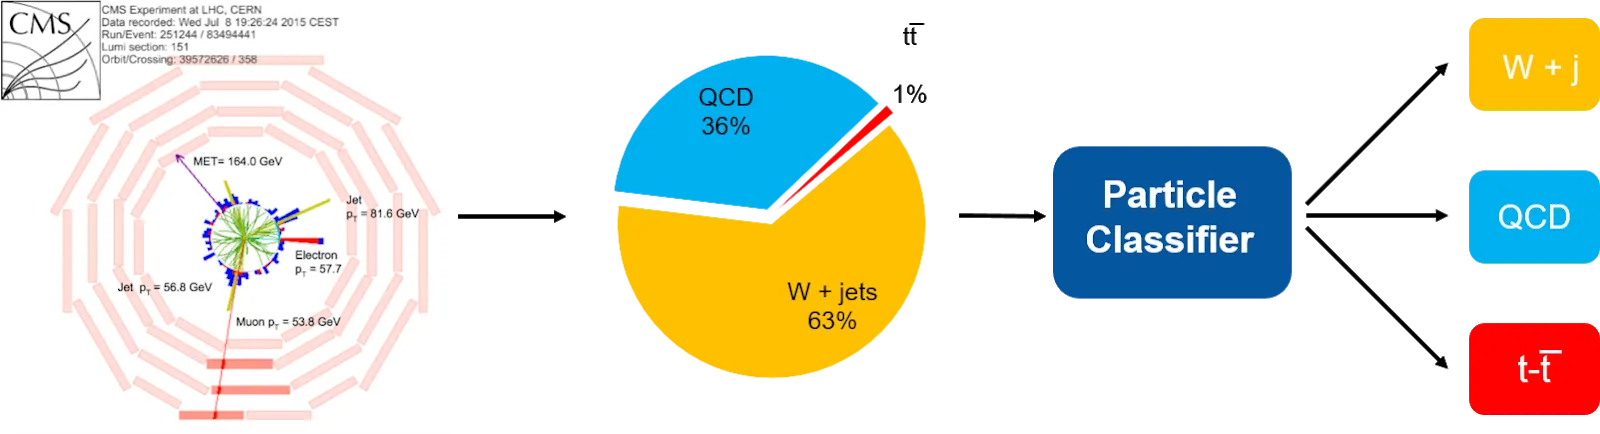
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo
Machine Learning Pipelines for High Energy Physics Using Apache Spark with BigDL and Analytics Zoo Topic: This post describes a data pipeline for a machine learning task of interest in high energy physics: building a particle classifier to improve event selection at the particle detectors. The pipeline is built using tools from the “Big Data
-
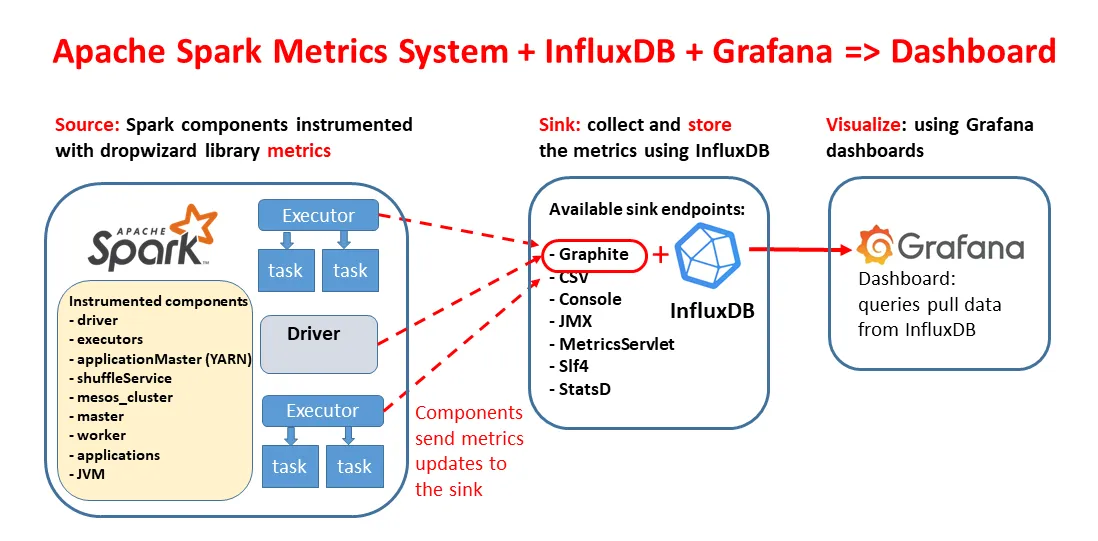
A Performance Dashboard for Apache Spark
A Performance Dashboard for Apache Spark Topic: This post dives into the steps for deploying a performance dashboard for Apache Spark, using Spark metrics system instrumentation, InfluxDB and Grafana. What problem does it solve: The dashboard can provide important insights for performance troubleshooting and online monitoring of Apache Spark workloads. In particular when running Spark
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
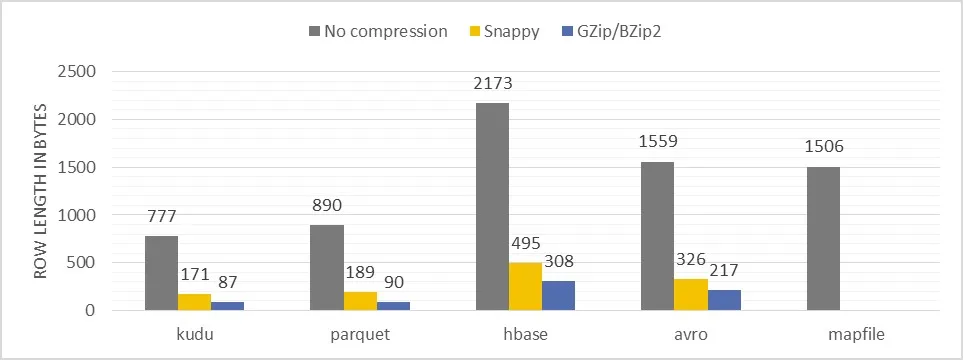
Performance comparison of different file formats and storage engines in the Hadoop ecosystem
Performance comparison of different file formats and storage engines in the Hadoop ecosystem TOPIC This post reports performance tests for a few popular data formats and storage engines available in the Hadoop ecosystem: Apache Avro, Apache Parquet, Apache HBase and Apache Kudu. This exercise evaluates space efficiency, ingestion performance, analytic scans and random data lookup