
Tag: Hadoop
-
Benchmarking Apache Kafka on OpenStack VM’s
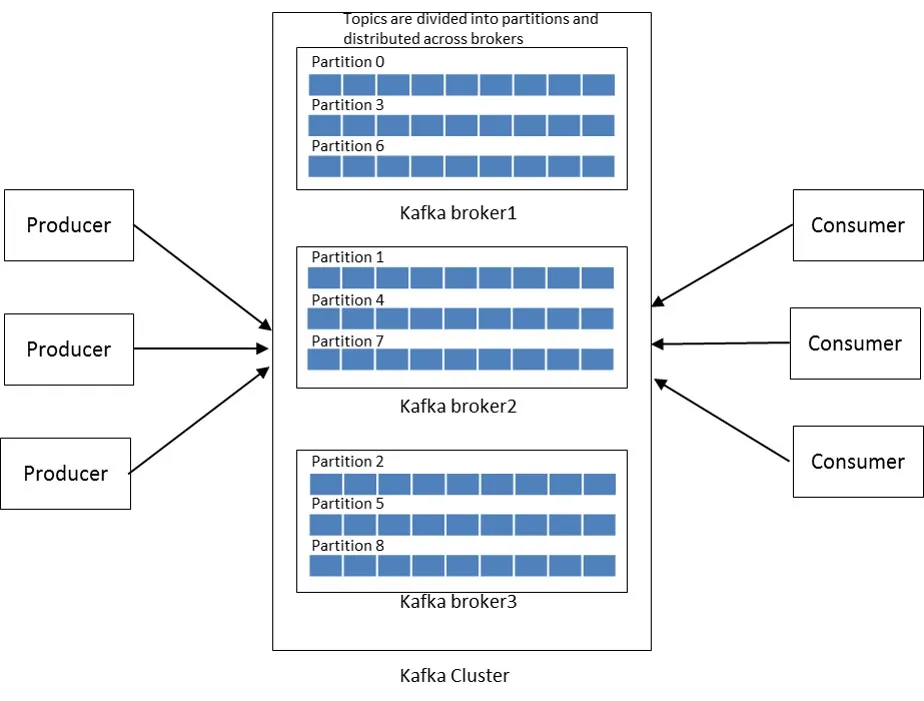
Benchmarking Apache Kafka on OpenStack VM’s I have been wanting to test Apache Kafka for sometime now and finally got around to it! In this blog post I give a very short introduction on what is Kafka, installation & configuration of Kafka cluster and finally benchmarking few near real-world scenarios on OpenStack VM's What is
-
Offline analysis of HDFS metadata
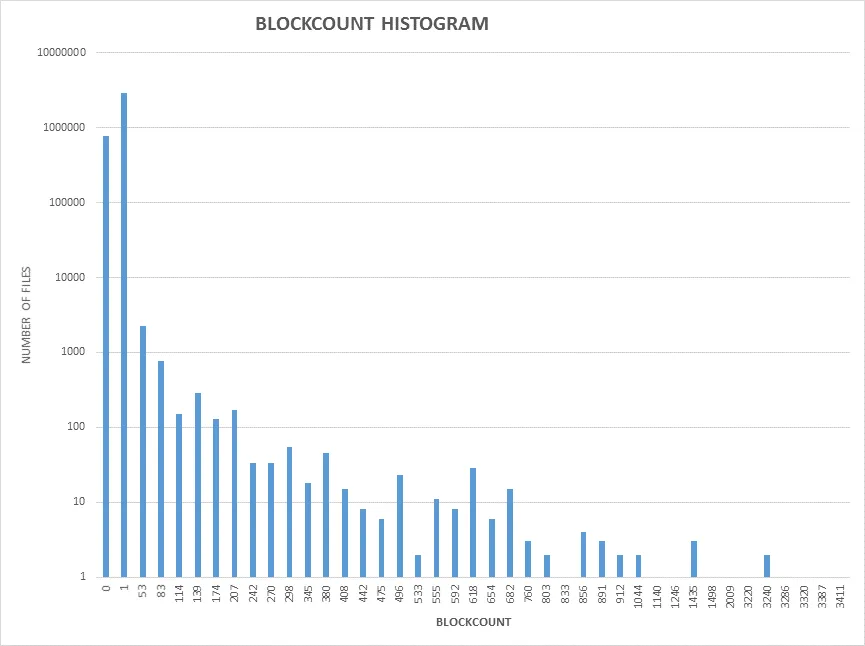
Offline analysis of HDFS metadata Introduction HDFS is part of the core Hadoop ecosystem and serves as a storage layer for the Hadoop computational frameworks like Spark, MapReduce. Like other distributed file systems, HDFS is based on an architecture where namespace is decoupled from the data. The namespace contains the file system metadata which is
-
Using Tiered Storage in Alluxio
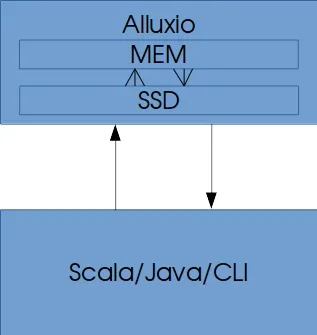
Using Tiered Storage in Alluxio Introduction Alluxio is an open source memory speed virtual distributed storage system. A brief overview of Alluxio has been covered in a previous blog. This post will cover one of the most powerful features of Alluxio, which is its tiered storage capabilities. Tiered storage allows the Alluxio volume to be
-
Experiences of Using Alluxio with Spark
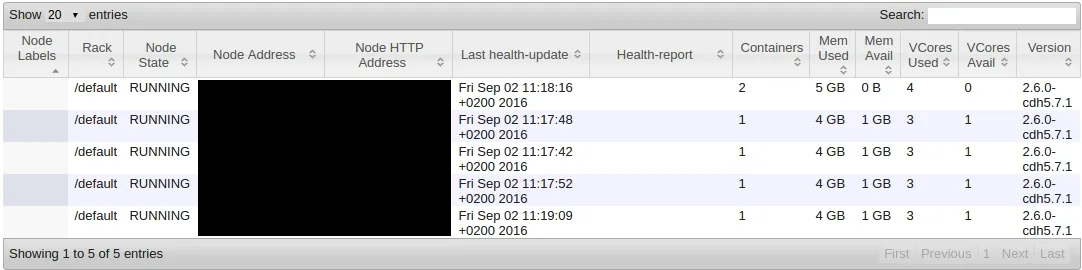
Experiences of Using Alluxio with Spark Introduction Alluxio refers to itself as an “Open Source Memory Speed Virtual Distributed Storage” platform. It sits between the storage and processing framework layers in the distributed computing ecosystem and claims to heavily improve performance when multiple jobs are reading/writing from/to the same data. This post will cover some
-

Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark Introduction In the part 2 of 'Integrating Hadoop and Elasticsearch' blogpost series we look at bridging Apache Spark and Elasticsearch. I assume that you have access to Hadoop and Elasticsearch clusters and you are faced with the challenge of
-
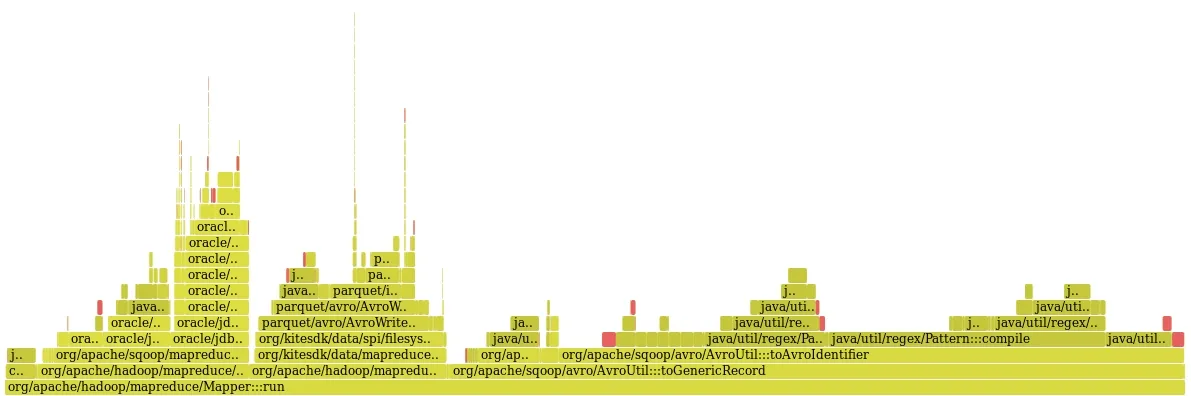
Hadoop performance troubleshooting with stack tracing, an introduction.
Hadoop performance troubleshooting with stack tracing, an introduction. Topic: This post is about profiling and performance tuning of distributed workloads and in particular Hadoop applications. You will learn of a profiler application we have developed and how it has successfully been applied to tuning Sqoop to improve the throughput of data transfer from Oracle to
-
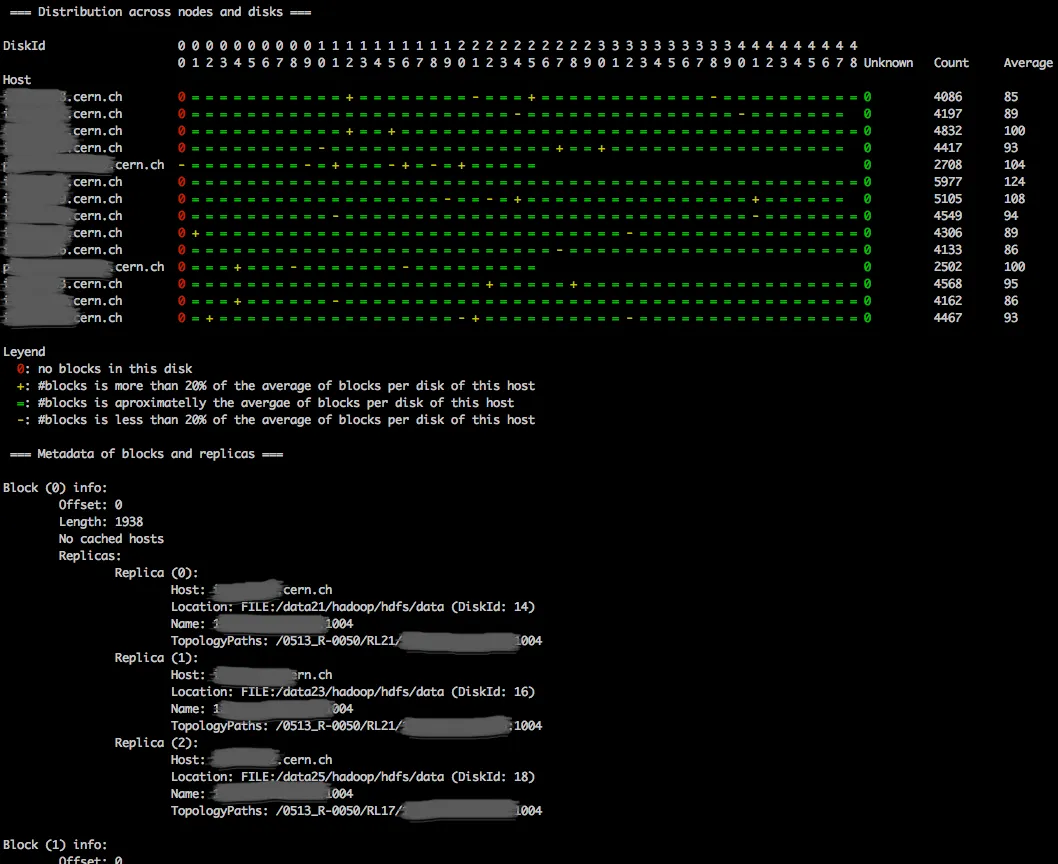
Tool to visualise block distribution on Hadoop (HDFS) cluster
Tool to visualise block distribution on Hadoop (HDFS) cluster Distributed systems always bring new challenges for administrators and users. This is the case with HDFS, the default distributed file system that Hadoop uses for storing data. In order to face these challenges, tools to facilitate administration and usage of these systems are developed. At CERN,
-
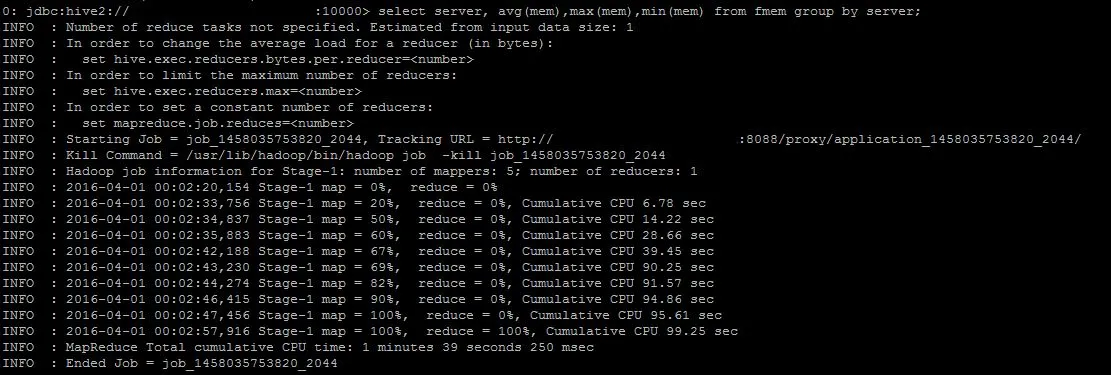
Integrating Hadoop and Elasticsearch – Part 1 – Loading into and Querying Elasticsearch from Apache Hive
Integrating Hadoop and Elasticsearch – Part 1 – Loading into and Querying Elasticsearch from Apache Hive Introduction As more and more organisations are deploying Hadoop and Elasticsearch in tandem to satisfy batch analytics, real-time analytics and monitoring requirements, the need for tigher integration between Hadoop and Elasticsearch has never been more important. In this series