Category: Blog Post
-
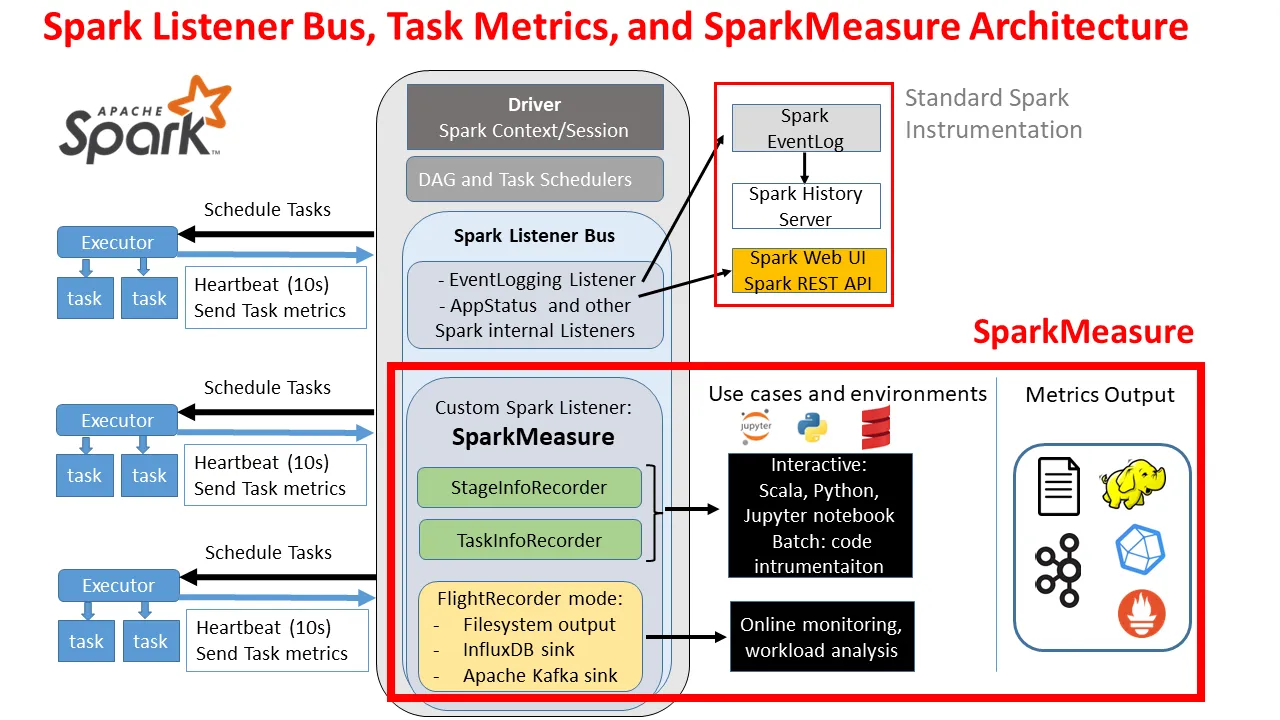
SparkMeasure, a tool for performance troubleshooting of Apache Spark workloads
SparkMeasure, a tool for performance troubleshooting of Apache Spark workloads SparkMeasure SparkMeasure simplifies the collection and analysis of Apache Spark task metrics data. It is also intended as a working example of how to use Spark listeners for collecting and processing Spark performance metrics. The work on sparkMeasure has been previously presented in this blog
-
Creating TLS certificates using Kubernetes API
Creating TLS certificates using Kubernetes API The purpose of this post is to explain the need of adding encryption to the network communications between containers, and how to achieve it at application level, creating Transport Layer Security (TLS) certificates with the already provided Kubernetes APIs. Is it necessary to add encryption between containers? When running
-
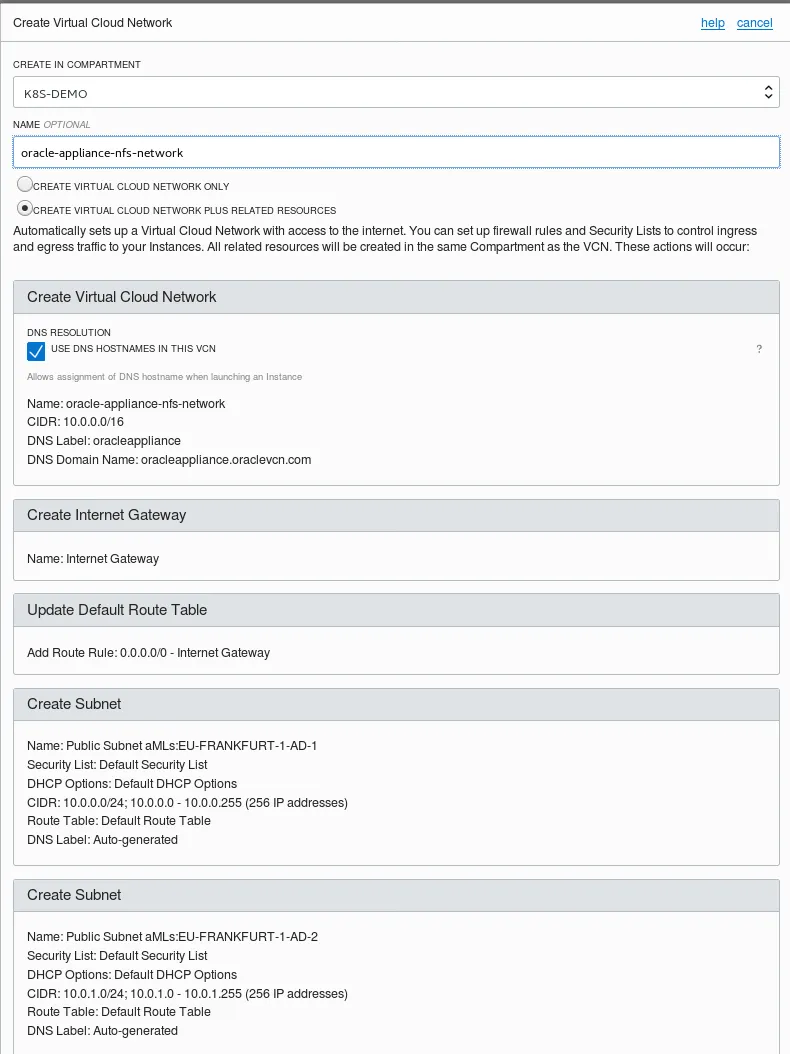
Setup NFS storage on Oracle Cloud Infrastructure using Linux Storage Appliance
Setup NFS storage on Oracle Cloud Infrastructure using Linux Storage Appliance As explained in another blog post, Oracle is becoming a cloud company. In this post I'm gonna show you how to setup a NFS storage in the Oracle Cloud Infrastructure using Linux Storage Appliance. Prerequisites Setup NFS To achieve this we need to perform
-
Install Kubernetes on Oracle Cloud Infrastructure
Install Kubernetes on Oracle Cloud Infrastructure In the last year Oracle has changed a lot, moving with determination to the Cloud business. They increased their portfolio with IaaS, PaaS and SaaS solutions. In the context of Openlab collaboration between Oracle and CERN we have been testing some of these cloud solutions. Oracle Cloud Infrastructure (
-
HAProxy Canary Deployment
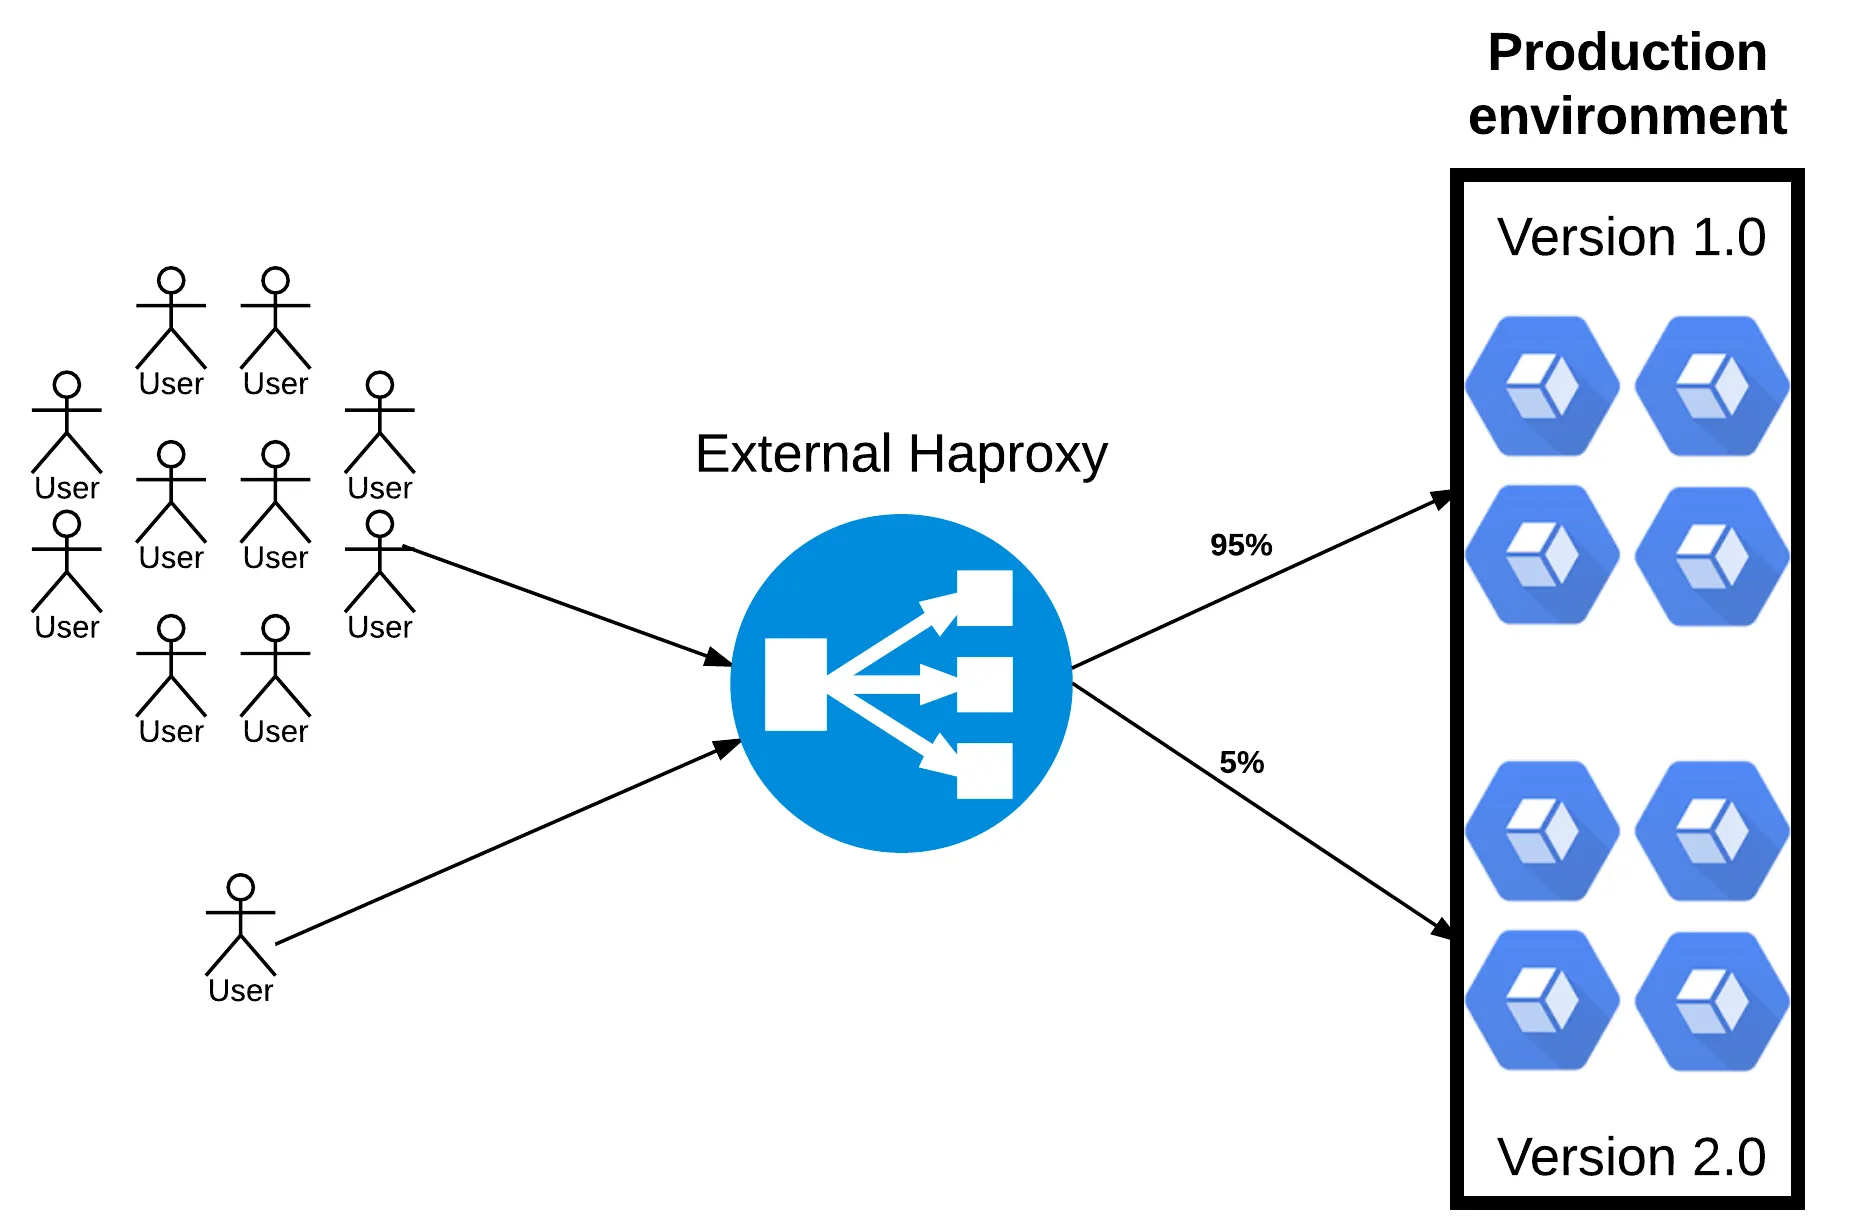
HAProxy Canary Deployment Canary deployment is a way to test a new release of a software rolling it only for a small sub set of users. In this post I'll show how at CERN, in the Middleware section of Database group, we configure our HAProxy setup to work as canary deployment. I'll give a brief
-
HAProxy High Availability Setup
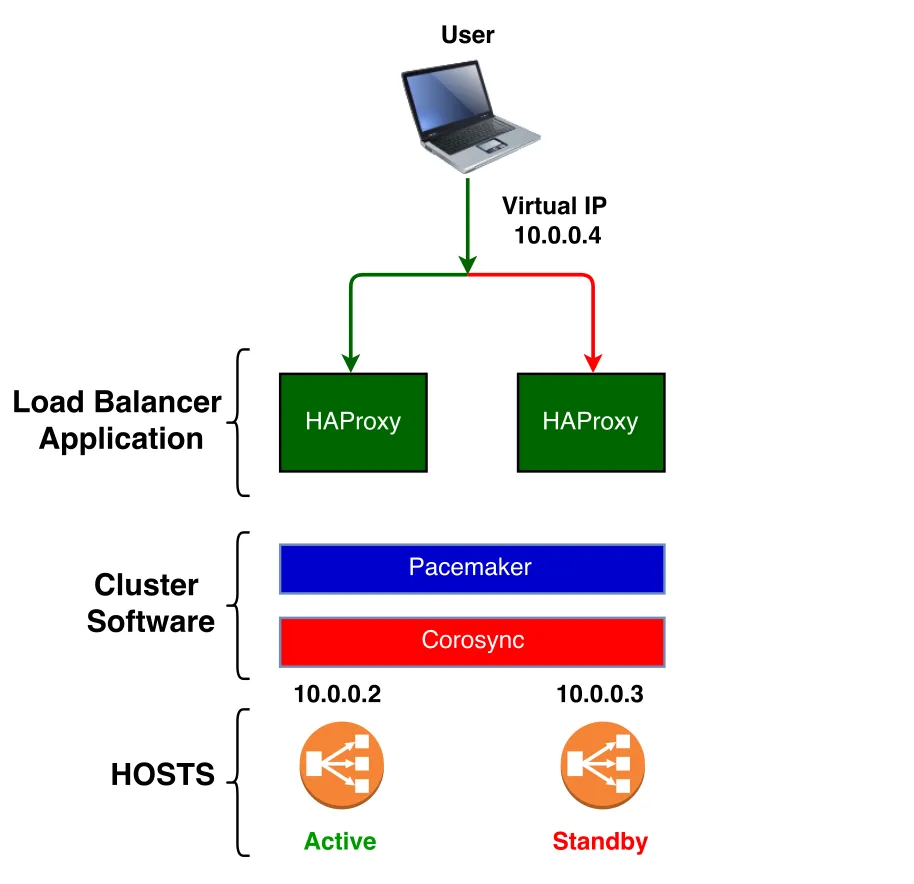
HAProxy High Availability Setup In the modern world where everyone wants to be always connected, High Availability became one of the most important feature for a system. For example if you are running a system you don’t want a failure in one piece of your architecture impacts the whole system. You have to make all
-
Intelligent monitoring with a new general-purpose metrics monitor
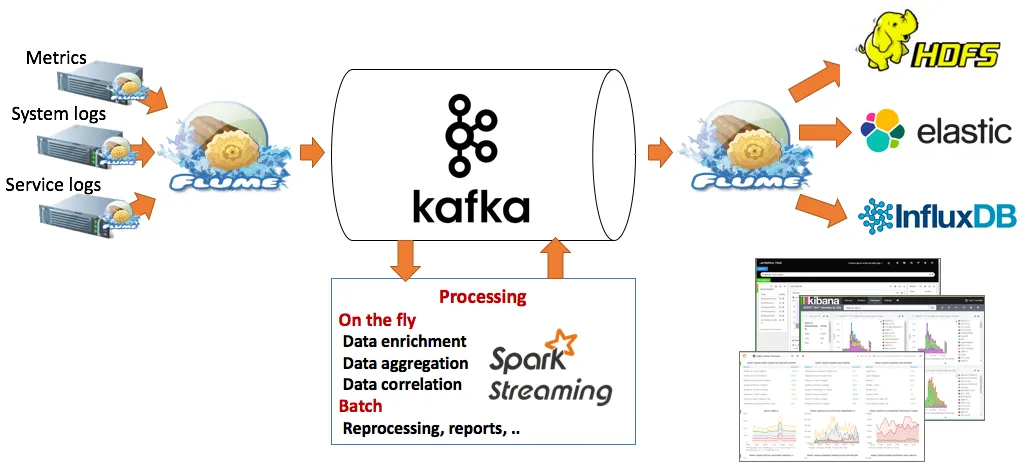
Intelligent monitoring with a new general-purpose metrics monitor In the database team at CERN, we have developed a general-purpose metrics monitor, a missing part in our next generation monitoring infrastructure. In the implemented metrics monitor, metrics can come from several sources like Apache Kafka, new metrics can be defined combining other metrics, different analysis can
-

Performance Analysis of a CPU-Intensive Workload in Apache Spark
Performance Analysis of a CPU-Intensive Workload in Apache Spark Topic: This post is about techniques and tools for measuring and understanding CPU-bound and memory-bound workloads in Apache Spark. You will find examples applied to studying a simple workload consisting of reading Apache Parquet files into a Spark DataFrame. Why are the topics discussed here relevant
-
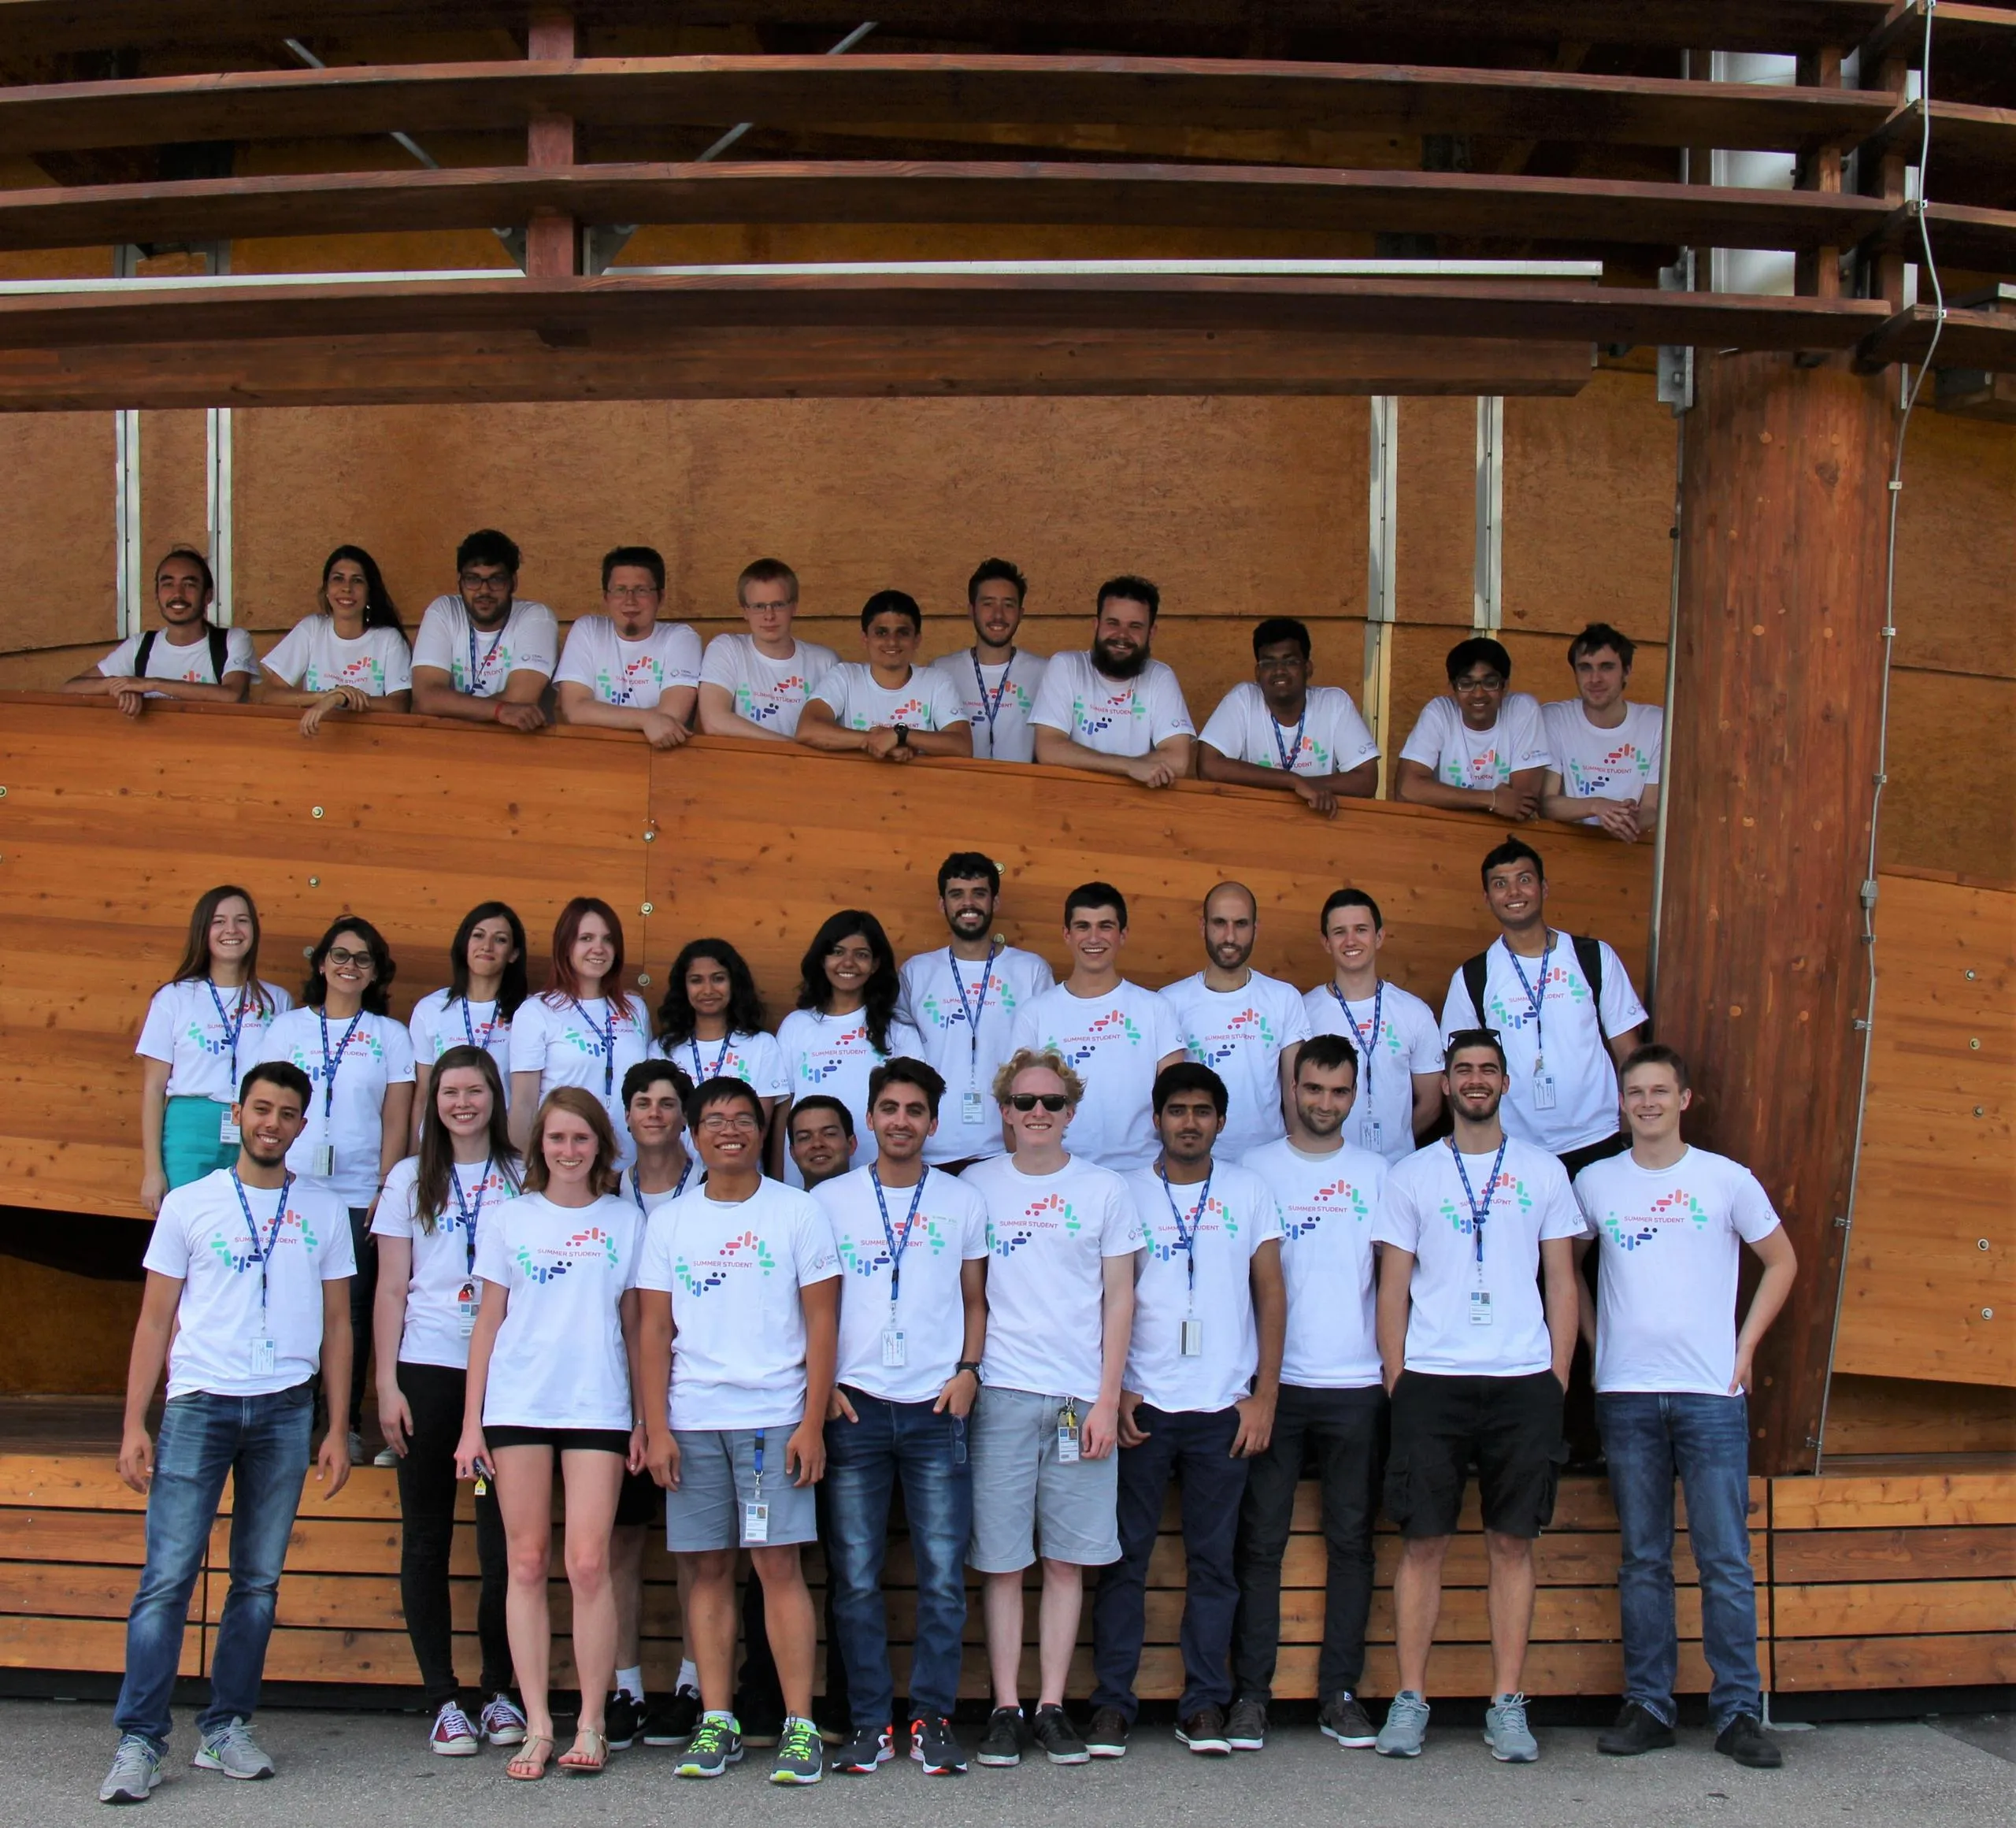
My experiences from the CERN openlab Summer Student Programme 2017
My experiences from the CERN openlab Summer Student Programme 2017 Hello everyone, Now I am back in Norway, and it is time for looking back and reminisce about my amazing and memorable summer at CERN. So, today I will tell you about my experiences from my Summer Internship. I got the happy message that I
-
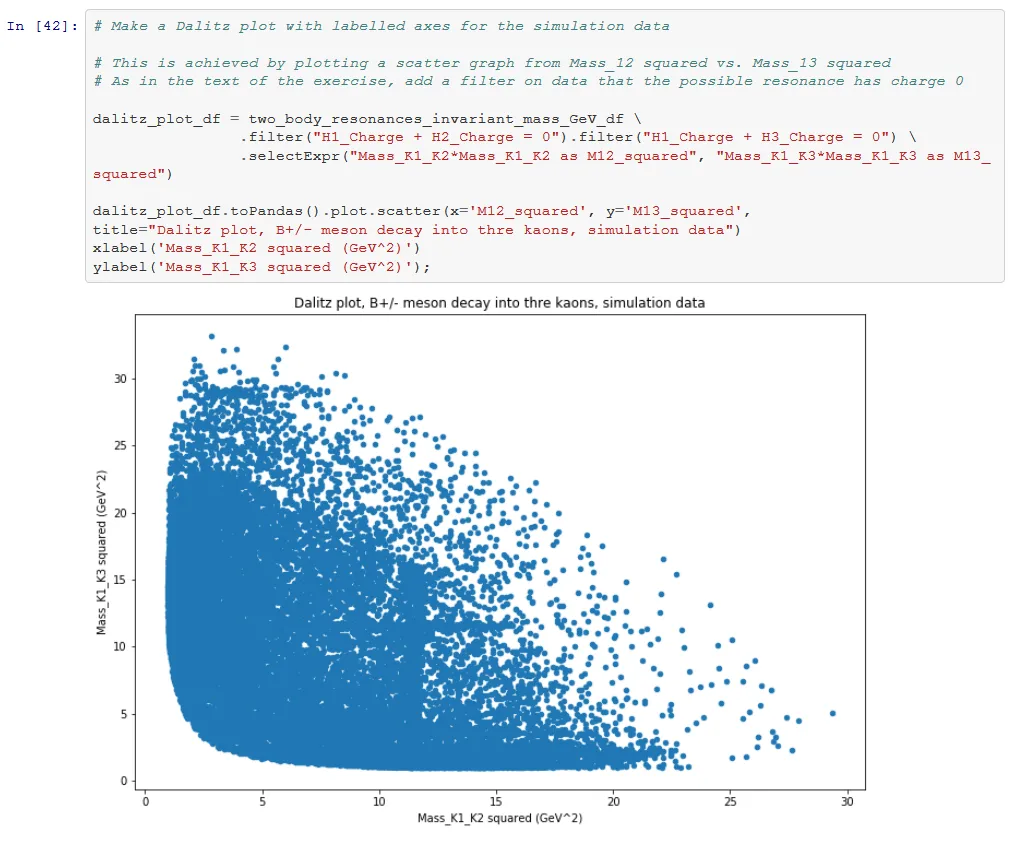
Apache Spark and CERN Open Data Analysis, an Example
Apache Spark and CERN Open Data Analysis, an Example This is a short post introducing a notebook that you can use to play with a simple analysis of High Energy Physics (HEP) data using CERN open data and Apache Spark. The idea for this work started with a concept for a technology demonstrator of some