
Category: Blog Post
-
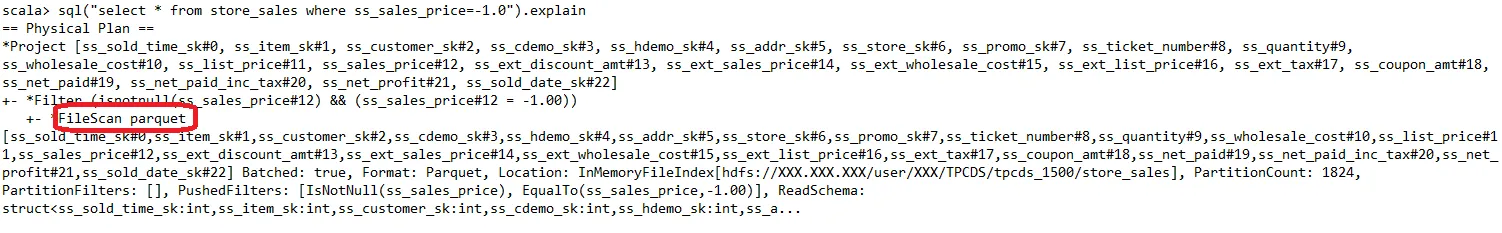
Diving into Spark and Parquet Workloads, by Example
Diving into Spark and Parquet Workloads, by Example Topic: In this post you can find a few simple examples illustrating important features of Spark when reading partitioned tables stored in Parquet, in particular with a focus on performance investigations. The main topics covered are: Motivations: The combination of Spark and Parquet currently is a very
-
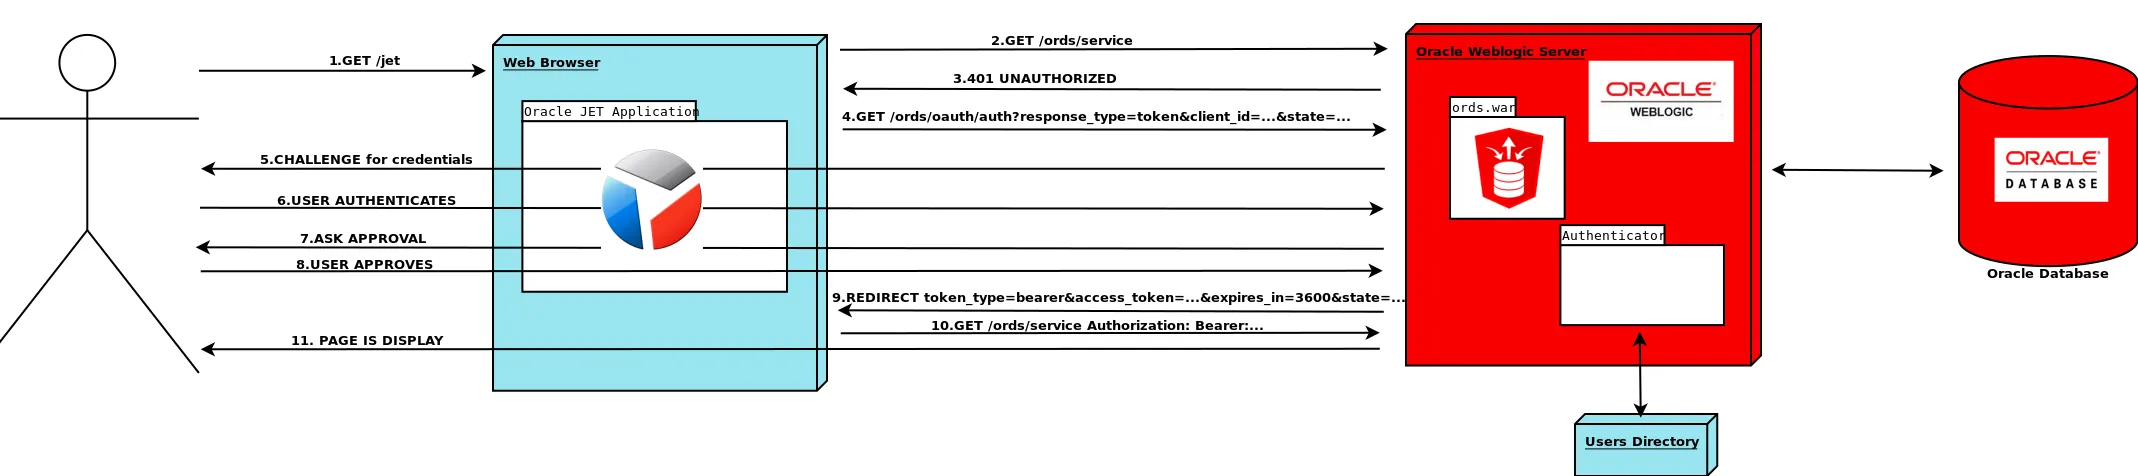
Oracle JET, ORDS & OAUTH2
Oracle JET, ORDS & OAUTH2 Hello there, Probably you are familiar with other Oracle developer tools and frameworks like APEX and ADF. But maybe you are less aware that Oracle entered into the Javascript rumble with the Oracle Javascript Extension Toolkit. Oracle JET is a modular Javascript framework or toolkit formed by several popular Javascript
-
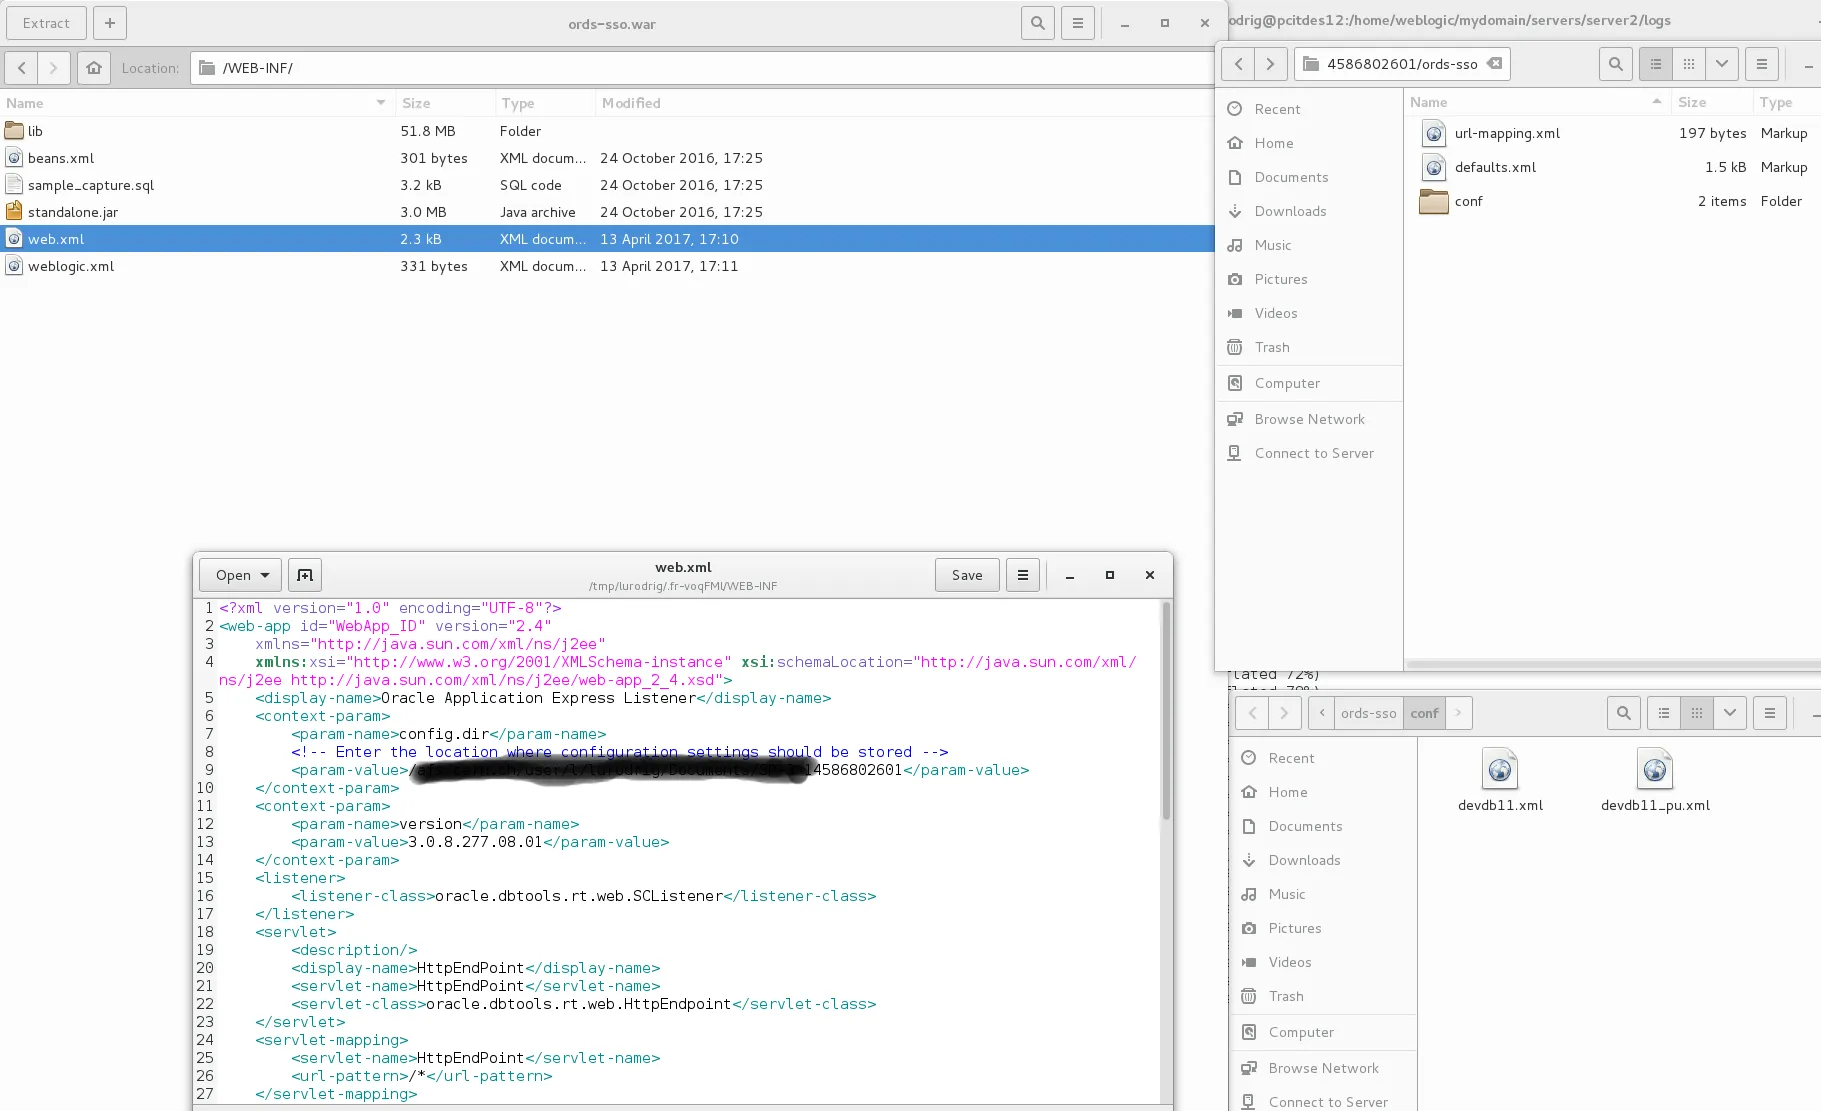
SSO for Oracle REST DataServices
SSO for Oracle REST DataServices Hello there, Recently I’ve started to dig into the ORDS authentication and more specifically in how to make it work against my Oracle WebLogic server authenticators. ORDS Service Definition The first step is to create or define a REST service in our Oracle database. The oracle-base.com guys have a fantastic
-
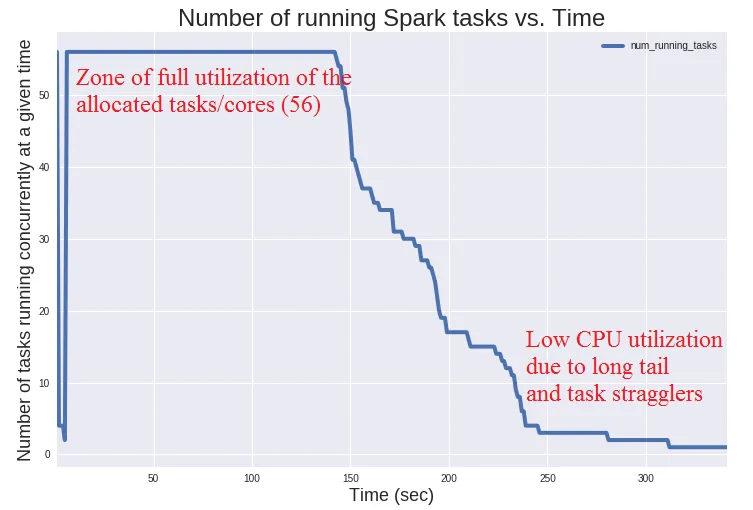
On Measuring Apache Spark Workload Metrics for Performance Troubleshooting
On Measuring Apache Spark Workload Metrics for Performance Troubleshooting Topic: This post is about measuring Apache Spark workload metrics for performance investigations. In particular you can find the description of some practical techniques and a simple tool that can help you with Spark workload metrics collection and performance analysis. The post is released with accompanying
-
Performance comparison of different file formats and storage engines in the Hadoop ecosystem
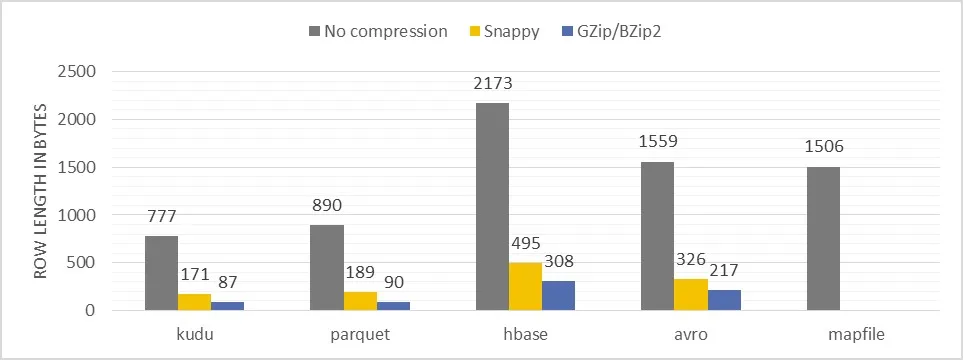
Performance comparison of different file formats and storage engines in the Hadoop ecosystem TOPIC This post reports performance tests for a few popular data formats and storage engines available in the Hadoop ecosystem: Apache Avro, Apache Parquet, Apache HBase and Apache Kudu. This exercise evaluates space efficiency, ingestion performance, analytic scans and random data lookup
-
Upgrading my Oracle JVM Diagnostics Agents.
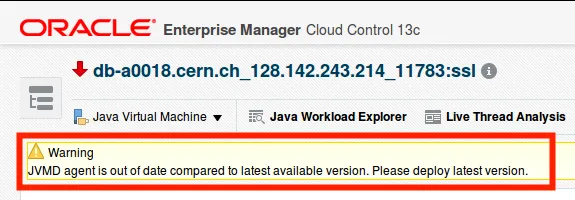
Upgrading my Oracle JVM Diagnostics Agents. Hello there, Last week one of the users of our CERN Java PaaS told me something like this: Hey Luis, you know? It looks like my application is faster on my PC than in your servers… mmm, OK, it could be possible regarding that our VMs are not very
-
Starting up with the Oracle Java Cloud Services.
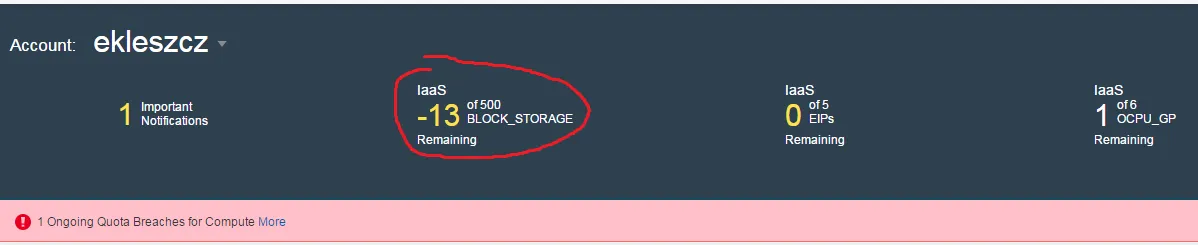
Starting up with the Oracle Java Cloud Services. Hello everyone, In this entry I would like to share my experiences using Oracle Java Cloud Service, especially securing the application environment. I will show you some issues that I encountered during standard process of setting up environment. I will also explain some basic concepts that are
-
IPython/Jupyter SQL Magic Functions for PySpark
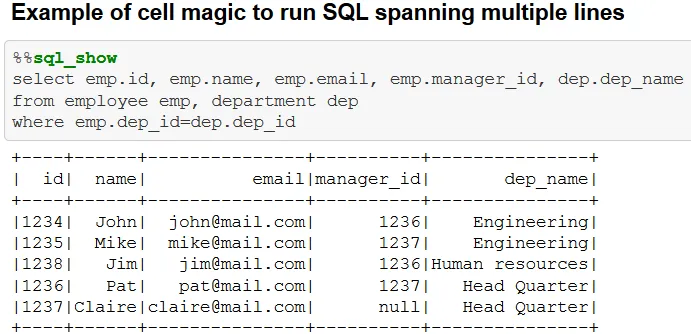
IPython/Jupyter SQL Magic Functions for PySpark Topic: this post is about a simple implementation with examples of IPython custom magic functions for running SQL in Apache Spark using PySpark and Jupyter notebooks. If you are already famialiar with Apache Spark and Jupyter notebooks may want to go directly to the links with the example notebook
-
Darwin and Hadoop join forces to improve a face recognition algorithm
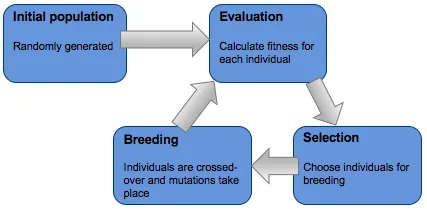
Darwin and Hadoop join forces to improve a face recognition algorithm In this blog entry we introduce evolutionary algorithms and an integration between an evolutionary computation tool, ECJ, and Apache Hadoop. This research aims at speeding up the evaluation of solutions by distributing the workload among a cluster of machines. Finally, we make sense out
-

Testing a Small Query Language in Python with Hypothesis
Testing a Small Query Language in Python with Hypothesis Hypothesis is an implementation of Property-based testing for Python, similar to QuickCheck in Haskell/Erlang and test.check in Clojure (among others). Basically, it allows the programmer to formulate invariants about their programs, and have an automated system attempt to generate counter-examples that invalidates them. A Small Query