Category: Blog Post
-
Custom Flume sources for ingesting data from database tables and log files
Custom Flume sources for ingesting data from database tables and log files On our way to build a central repository that stores consolidated audit and log data generated by the databases, we needed to develop several components that will help us to achieve such purpose. In this case, we will be talking about two custom
-
Benchmarking Apache Kafka on OpenStack VM’s
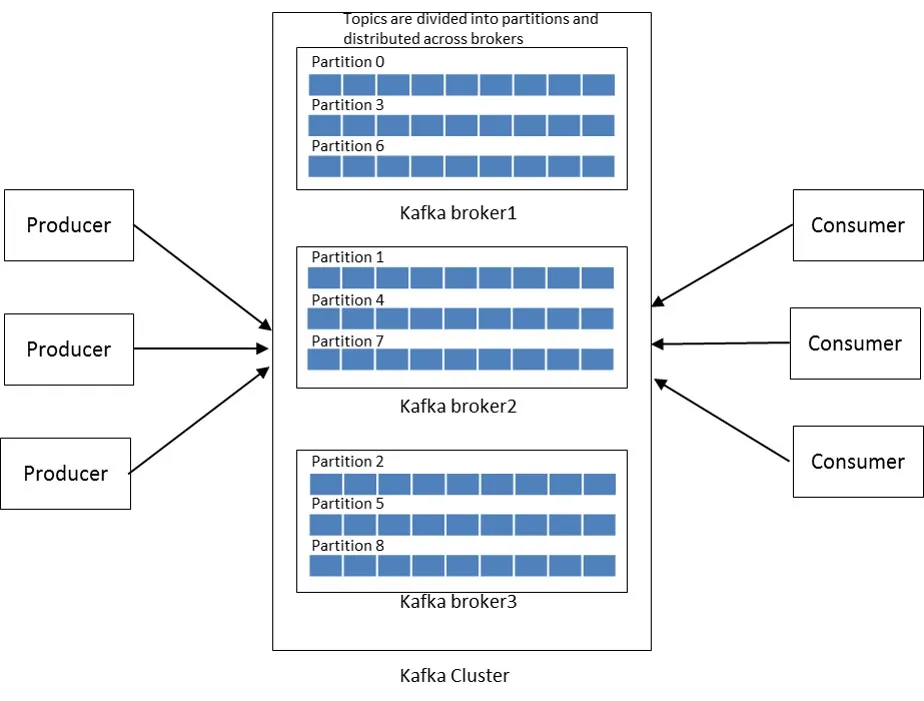
Benchmarking Apache Kafka on OpenStack VM’s I have been wanting to test Apache Kafka for sometime now and finally got around to it! In this blog post I give a very short introduction on what is Kafka, installation & configuration of Kafka cluster and finally benchmarking few near real-world scenarios on OpenStack VM's What is
-
Offline analysis of HDFS metadata
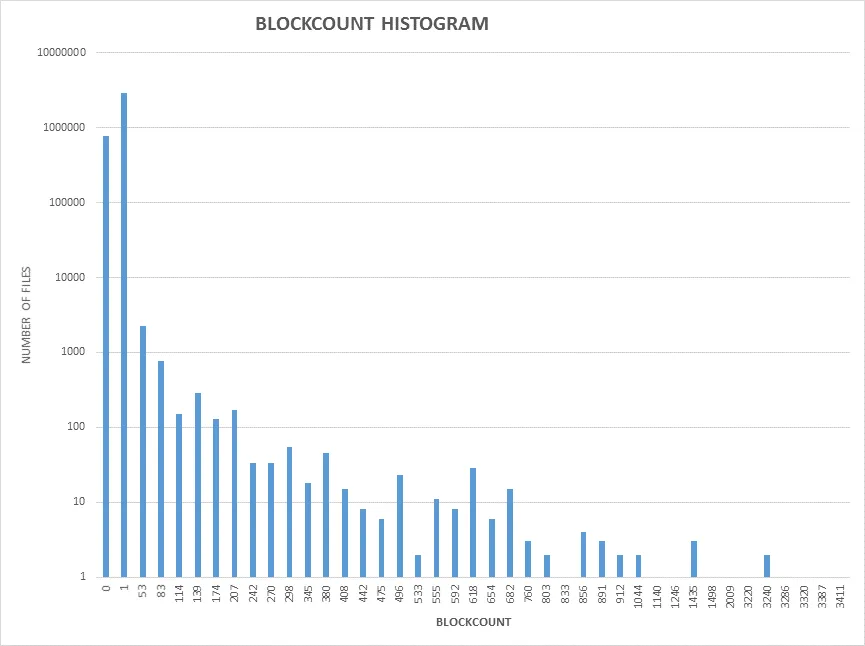
Offline analysis of HDFS metadata Introduction HDFS is part of the core Hadoop ecosystem and serves as a storage layer for the Hadoop computational frameworks like Spark, MapReduce. Like other distributed file systems, HDFS is based on an architecture where namespace is decoupled from the data. The namespace contains the file system metadata which is
-
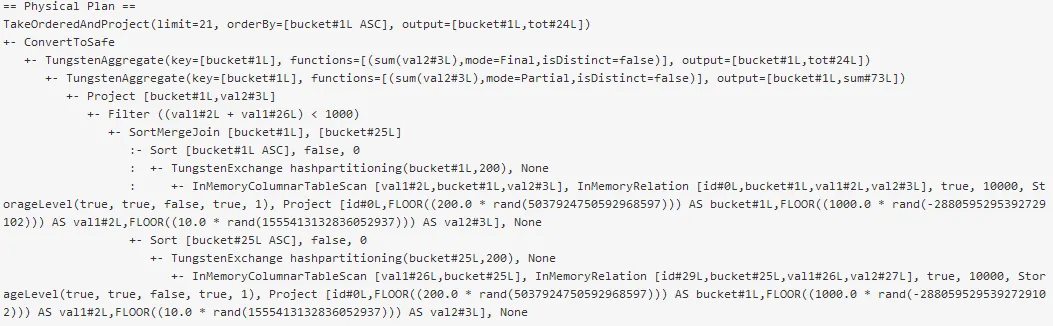
Apache Spark 2.0 Performance Improvements Investigated With Flame Graphs
Apache Spark 2.0 Performance Improvements Investigated With Flame Graphs Topic: This post is about performance optimizations introduced in Apache Spark 2.0, in particular whole-stage code generation. A test case is introduced and investigated with diagnostic tools. Introduction: performance troubleshooting of a slow query using parallel query execution in a Hadoop cluster The idea for this
-
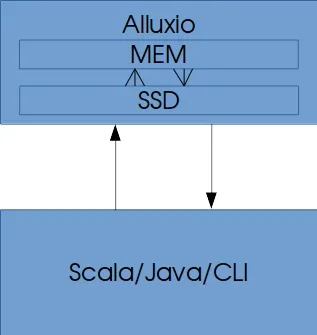
Using Tiered Storage in Alluxio
Using Tiered Storage in Alluxio Introduction Alluxio is an open source memory speed virtual distributed storage system. A brief overview of Alluxio has been covered in a previous blog. This post will cover one of the most powerful features of Alluxio, which is its tiered storage capabilities. Tiered storage allows the Alluxio volume to be
-
Java web application based on OAuth2
Java web application based on OAuth2 Hello, Last week I've investigated how does OAuth2 protocol works and developed a Proof of Concept (PoC) in Java. In this post I would like to show you how effortlessly develop simple client-server application using OAuth 2.0 standard for authorization of protected resources placed on a server. Before we
-
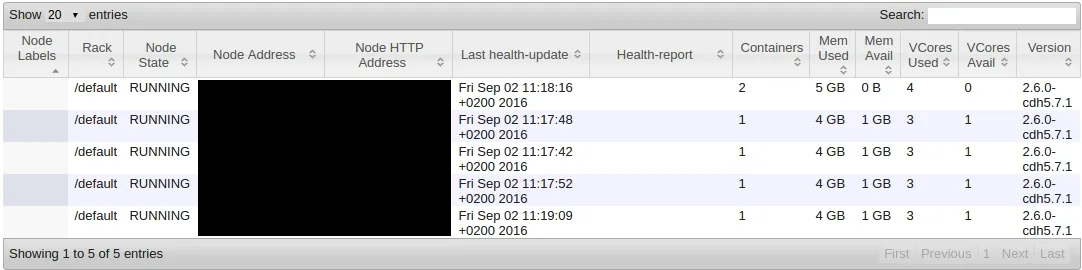
Experiences of Using Alluxio with Spark
Experiences of Using Alluxio with Spark Introduction Alluxio refers to itself as an “Open Source Memory Speed Virtual Distributed Storage” platform. It sits between the storage and processing framework layers in the distributed computing ecosystem and claims to heavily improve performance when multiple jobs are reading/writing from/to the same data. This post will cover some
-
A neural network scoring engine in PL/SQL for recognizing handwritten digits
A neural network scoring engine in PL/SQL for recognizing handwritten digits Topic: In this post, you will find an example of how to build and deploy a basic artificial neural network scoring engine using PL/SQL. This post is intended for learning purposes, in particular for Oracle practitioners who want a hands-on introduction to neural networks.
-
Real-time visualisation of Hadoop resources
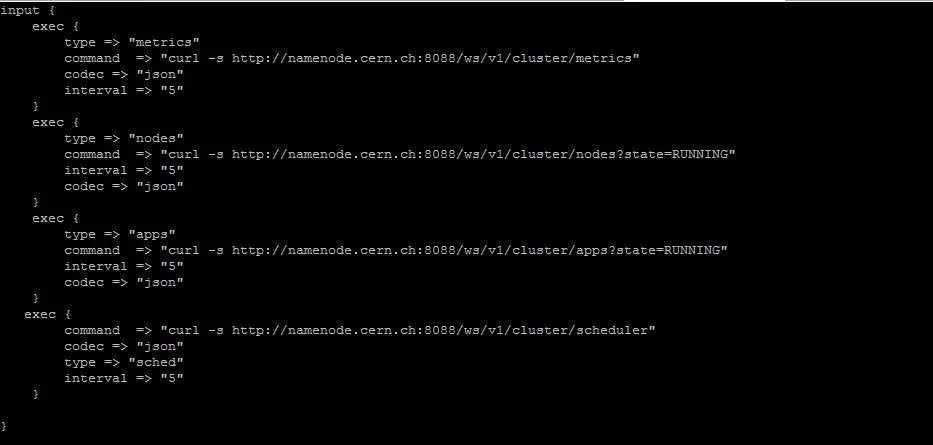
Real-time visualisation of Hadoop resources At CERN we run multiple Hadoop clusters to satisfy demanding requirements from our experiments and accelerator communities. The usage and criticality of the clusters are increasing dramatically as more users are looking at Hadoop to process and archive the vast amounts of data coming out of LHC. Sometimes, we as
-
IPython/Jupyter Notebooks for Oracle
IPython/Jupyter Notebooks for Oracle Topic: In this short post you can find examples of how to use IPython/Jupyter notebooks for running SQL on Oracle. IPython/Jupyter notebooks are one of the leading free platforms for data analysis, with many advantages, notably the interactive web-based interface and a large ecosystem of readily available packages for data analysis