Category: Blog Post
-
Linux BPF/bcc for Oracle Tracing
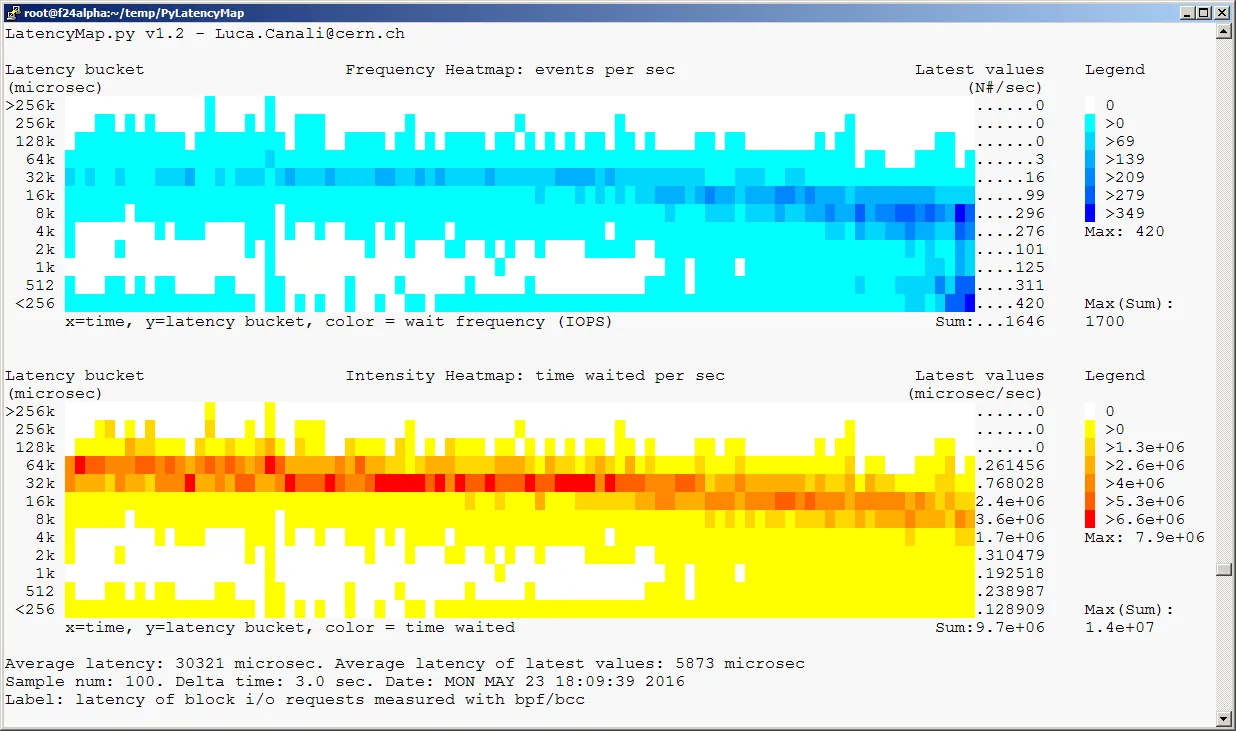
Linux BPF/bcc for Oracle Tracing Topic: In this post you will find a short discussion and pointers to the code of a few sample scripts that I have written using Linux BPF/bcc and uprobes for Oracle tracing. Previous work and motivations Tools for dynamic tracing are very useful for troubleshooting and internals investigations of Oracle
-
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark
Integrating Hadoop and Elasticsearch – Part 2 – Writing to and Querying Elasticsearch from Apache Spark Introduction In the part 2 of 'Integrating Hadoop and Elasticsearch' blogpost series we look at bridging Apache Spark and Elasticsearch. I assume that you have access to Hadoop and Elasticsearch clusters and you are faced with the challenge of
-
IPython Notebooks for Querying Apache Impala
IPython Notebooks for Querying Apache Impala Topic: in this post you can find examples of how to get started with using IPython/Jupyter notebooks for querying Apache Impala. Apache Impala is an open source massively parallel processing (MPP) SQL Query Engine for Apache Hadoop. This post explores the use of IPython for querying Impala and generates
-
Hadoop performance troubleshooting with stack tracing, an introduction.
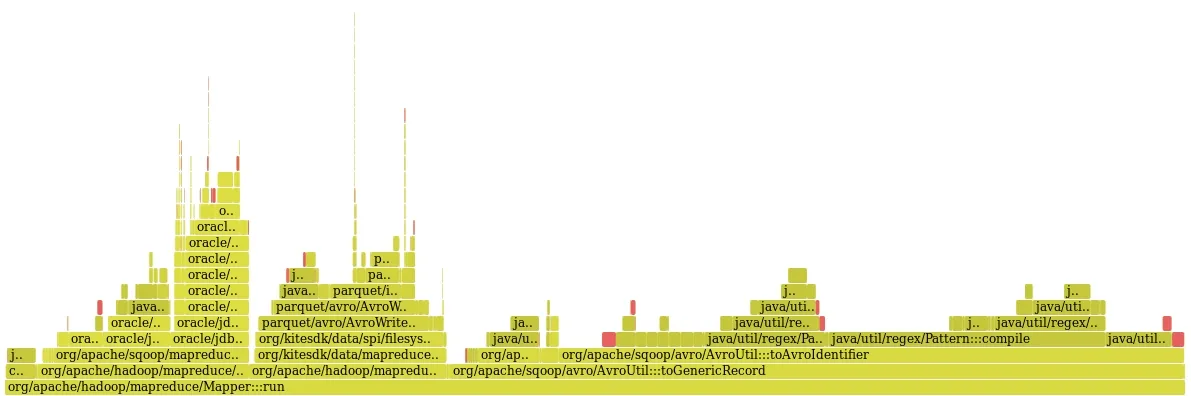
Hadoop performance troubleshooting with stack tracing, an introduction. Topic: This post is about profiling and performance tuning of distributed workloads and in particular Hadoop applications. You will learn of a profiler application we have developed and how it has successfully been applied to tuning Sqoop to improve the throughput of data transfer from Oracle to
-
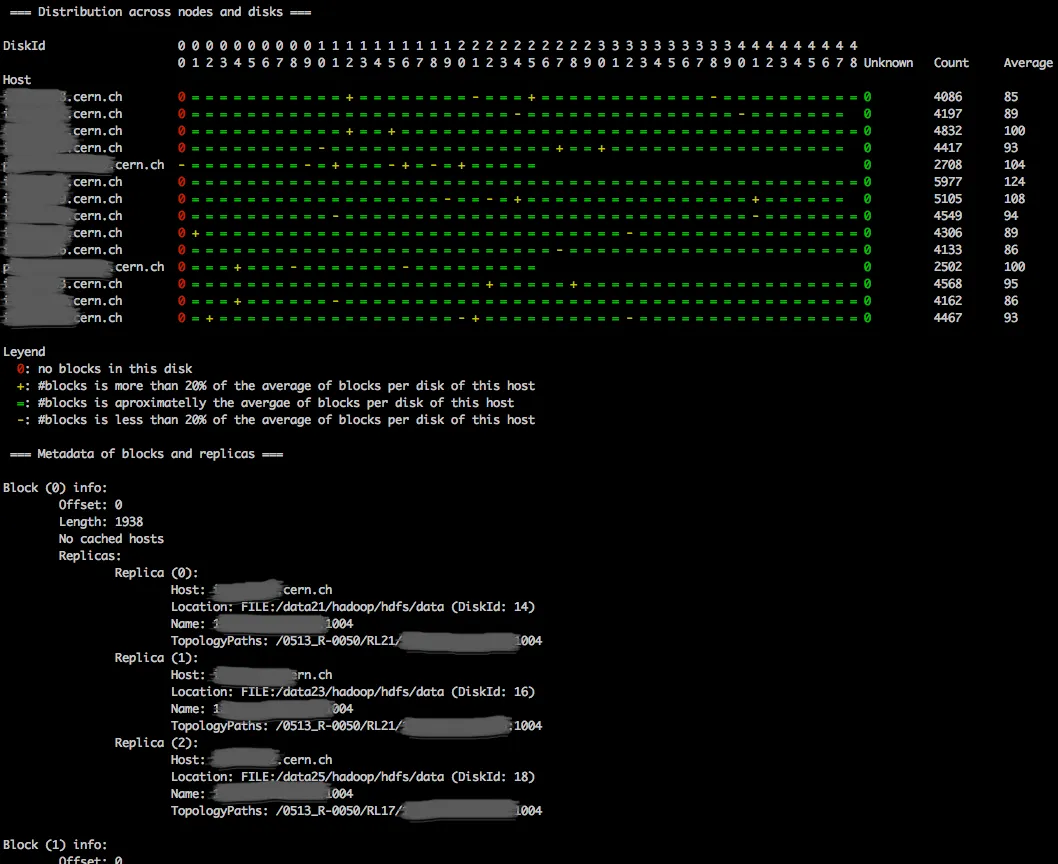
Tool to visualise block distribution on Hadoop (HDFS) cluster
Tool to visualise block distribution on Hadoop (HDFS) cluster Distributed systems always bring new challenges for administrators and users. This is the case with HDFS, the default distributed file system that Hadoop uses for storing data. In order to face these challenges, tools to facilitate administration and usage of these systems are developed. At CERN,
-
Datafile copy not found in control file during RMAN recovery
Datafile copy not found in control file during RMAN recovery The Problem: database restore fails with ORA-19571: datafile copy RECID xxx STAMP yyy not found in control file Our typical setup of Oracle databases consists of a primary RAC cluster along with a standby database, also in RAC configuration. We are taking RMAN database backups
-
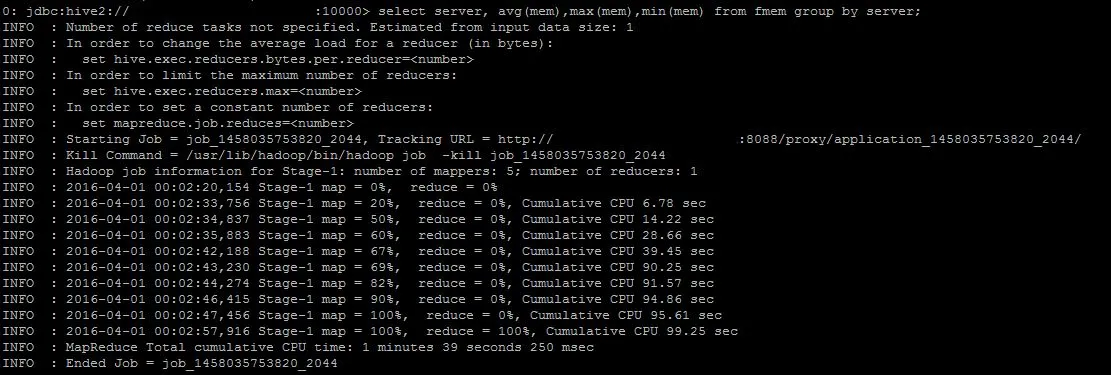
Integrating Hadoop and Elasticsearch – Part 1 – Loading into and Querying Elasticsearch from Apache Hive
Integrating Hadoop and Elasticsearch – Part 1 – Loading into and Querying Elasticsearch from Apache Hive Introduction As more and more organisations are deploying Hadoop and Elasticsearch in tandem to satisfy batch analytics, real-time analytics and monitoring requirements, the need for tigher integration between Hadoop and Elasticsearch has never been more important. In this series
-
PerfSheet.js: Oracle AWR Data Visualization in the Browser with JavaScript Pivot Charts
PerfSheet.js: Oracle AWR Data Visualization in the Browser with JavaScript Pivot Charts PerfSheet.js is a tool aimed at DBAs and Oracle performance analysts. It provides a simplified interface to extract and visualize AWR time series data in the browser using javascript. The reason for a tool like PerfSheet.js is to make the analysis of AWR
-
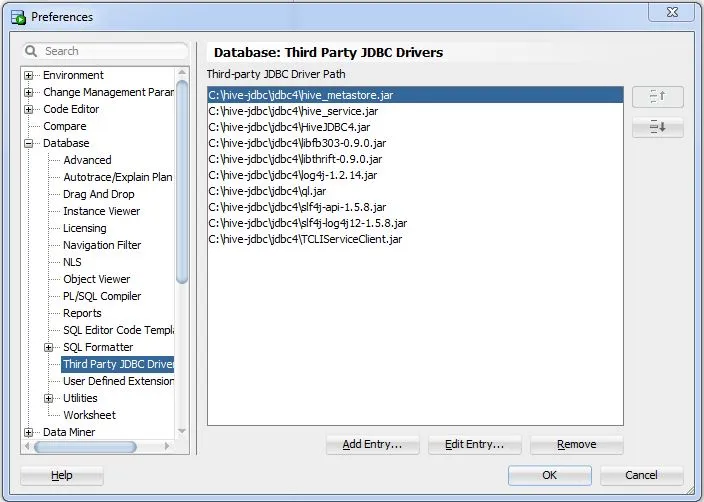
Using SQL Developer to access Apache Hive with kerberos authentication
Using SQL Developer to access Apache Hive with kerberos authentication With Hadoop implementations moving into mainstream, many of the Oracle DBA's are having to access SQL on Hadoop frameworks such as Apache Hive in their day to day operations. What better way is there to achieve this than using the familiar, functional and trusted Oracle
-
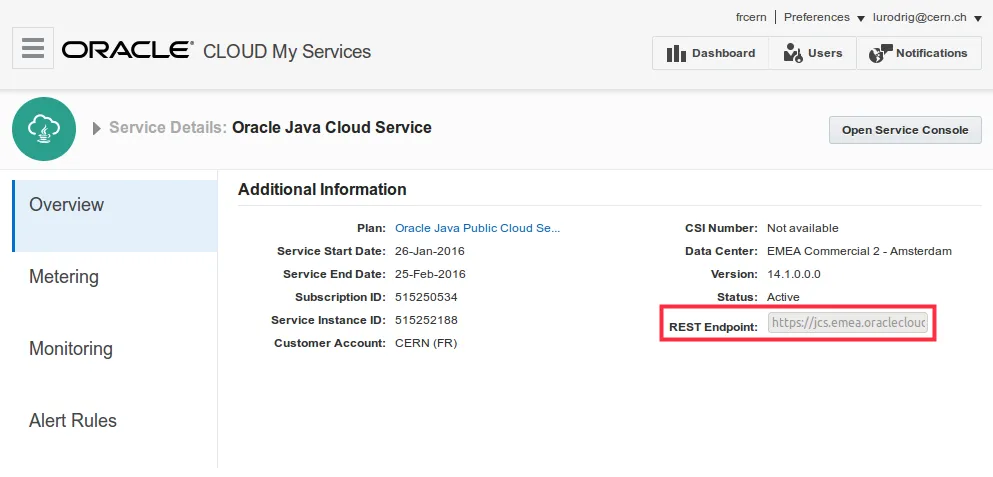
My first hour in the Oracle Cloud
My first hour in the Oracle Cloud Hello there! This week I received a mail from Oracle with something like this written on it: The powerful Java you love now available for Cloud deployment. Don’t miss this opportunity: a full-featured trial available at your fingertips! How could I resist??? So I clicked in the “Try